3DThinker & 4DThinker
Thinking with 3D and 4D latent imagery: spatial reasoning from a few views and from video用 3D 与 4D 潜在想象思考:从少数视角和视频出发的空间推理
Two papers teach a vision-language model to picture a scene before it reasons about it. 3DThinker (CVPR 2026) imagines a static scene from a few photos: before reasoning in words, the model writes twelve latent tokens, and a projector aligns their hidden states with the 3D features of VGGT; reinforcement learning then refines the whole answer. On MindCube-Tiny, Qwen2.5-VL-3B goes from 33.2 to 75.2. 4DThinker extends this to motion in video with dynamic latent mental imagery: inside its reasoning the model writes short latent blocks that picture how a highlighted object moves over time, learned from mask overlays its own frozen vision encoder embeds. On DSR-Bench, Qwen3-VL-32B goes from 28.0 to 62.0. Neither model needs depth maps, point clouds or extra modules at inference.
两篇论文让视觉语言模型先在脑中想象出场景,再对它推理。3DThinker(CVPR 2026)根据几张照片想象静态场景:在用文字推理之前,模型先写出 12 个潜在 token,由投影器把它们的隐状态对齐到 VGGT 的 3D 特征,再用强化学习优化整个回答。在 MindCube-Tiny 上,Qwen2.5-VL-3B 从 33.2 提升到 75.2。4DThinker 用动态潜在心理想象把这一思路推广到视频中的运动:模型在推理过程中写出若干小段潜在 token,想象被高亮的物体如何随时间运动,学习目标是它自己冻结的视觉编码器对掩码叠加图的嵌入。在 DSR-Bench 上,Qwen3-VL-32B 从 28.0 提升到 62.0。两个模型在推理时都不需要深度图、点云或额外模块。
3DThinker: spatial reasoning from a few views3DThinker:从少数几个视角做空间推理
Robots and cars see their surroundings through a handful of cameras, each covering part of the scene. Answering “what is behind the plant, seen from the second photo?” means imagining the whole scene from those partial views. Vision-language models pretrained on image–text data are still weak at this. The 3DThinker paper names two causes: they cannot extract the 3D geometry that the images contain, and their capacity for spatial imagination is limited.
机器人和汽车通过少数几个相机观察周围,每个相机只拍到场景的一部分。要回答“从第二张照片的视角看,植物后面是什么”,就得根据这些局部视角想象出整个场景。在图文数据上预训练的视觉语言模型在这类问题上仍然很弱。3DThinker 论文指出两个原因:模型无法提取图像中蕴含的 3D 几何信息,空间想象能力也有限。
Earlier fixes fall into two groups (Figure 2). The first reasons in pure text or with 2D visual cues, which cannot hold a complex layout. MindCube trains models to draw cognitive maps of the layout, but building them takes bird’s-eye-view annotations; Ego3D-VLM generates them automatically with GroundingDINO and Depth Anything V2, and fails where those models fail, on low-resolution or uncurated images. The second group feeds extra inputs such as point clouds or camera parameters, or calls external encoders and tools for depth maps or 3D tokens. That rules out settings with only monocular images, adds inference cost, and is not a skill of the model itself.
此前的改进分为两类(图 2)。第一类用纯文本或 2D 视觉线索推理,难以容纳复杂的空间布局。MindCube 训练模型画出布局的认知地图,但构建这些地图需要鸟瞰图(BEV)标注;Ego3D-VLM 借助 GroundingDINO 和 Depth Anything V2 自动生成认知地图,这些外部模型失效的地方(低分辨率或未经筛选的图像)它也随之失效。第二类额外输入点云、相机参数等模态,或调用外部编码器和工具获取深度图、3D token。这样就用不到只有单目图像的场景,推理开销也随之增加,而且这并不是模型自身的能力。
3DThinker sets three goals instead: learn 3D geometry directly from a few 2D images (3D-imaginable), without densely annotated data (annotation-free), and with no external prior or auxiliary model at inference (intrinsic). The model imagines the scene inside its own reasoning, as a block of latent tokens tied to the features of a 3D foundation model (Figure 1).
3DThinker 因此设定了三个目标:直接从少量 2D 图像中学习 3D 几何(可想象 3D),不依赖密集标注的数据(无需标注),推理时不借助外部先验或辅助模型(内生)。模型在自己的推理过程中想象场景,形式是一段与 3D 基础模型特征绑定的潜在 token(图 1)。
Input: a few photos of one scene and a question. Text or 2D cues leave the 3D layout implicit; 3DThinker imagines it.输入:同一场景的几张照片和一个问题。用文字或 2D 线索推理时 3D 布局是隐含的;3DThinker 则把它想象出来。 Imagine: before reasoning, the model writes a latent block, twelve <|latent_pad|> tokens between a start and an end token.想象:推理之前,模型先写出一段潜在 token:起止 token 之间是 12 个 <|latent_pad|>。 Align (Stage 1): a projector maps their hidden states and each view’s image tokens onto VGGT’s 1374 × 2048 features of that view.对齐(阶段 1):投影器把它们的隐状态与每个视角的图像 token 映射到 VGGT 在该视角上的 1374 × 2048 特征。 Reason (Stage 2): reasoning and answer follow the latents; GRPO scores eight rollouts by r3D + rformat + rans.推理(阶段 2):推理与答案写在潜在 token 之后;GRPO 对 8 条轨迹按 r3D + rformat + rans 打分。
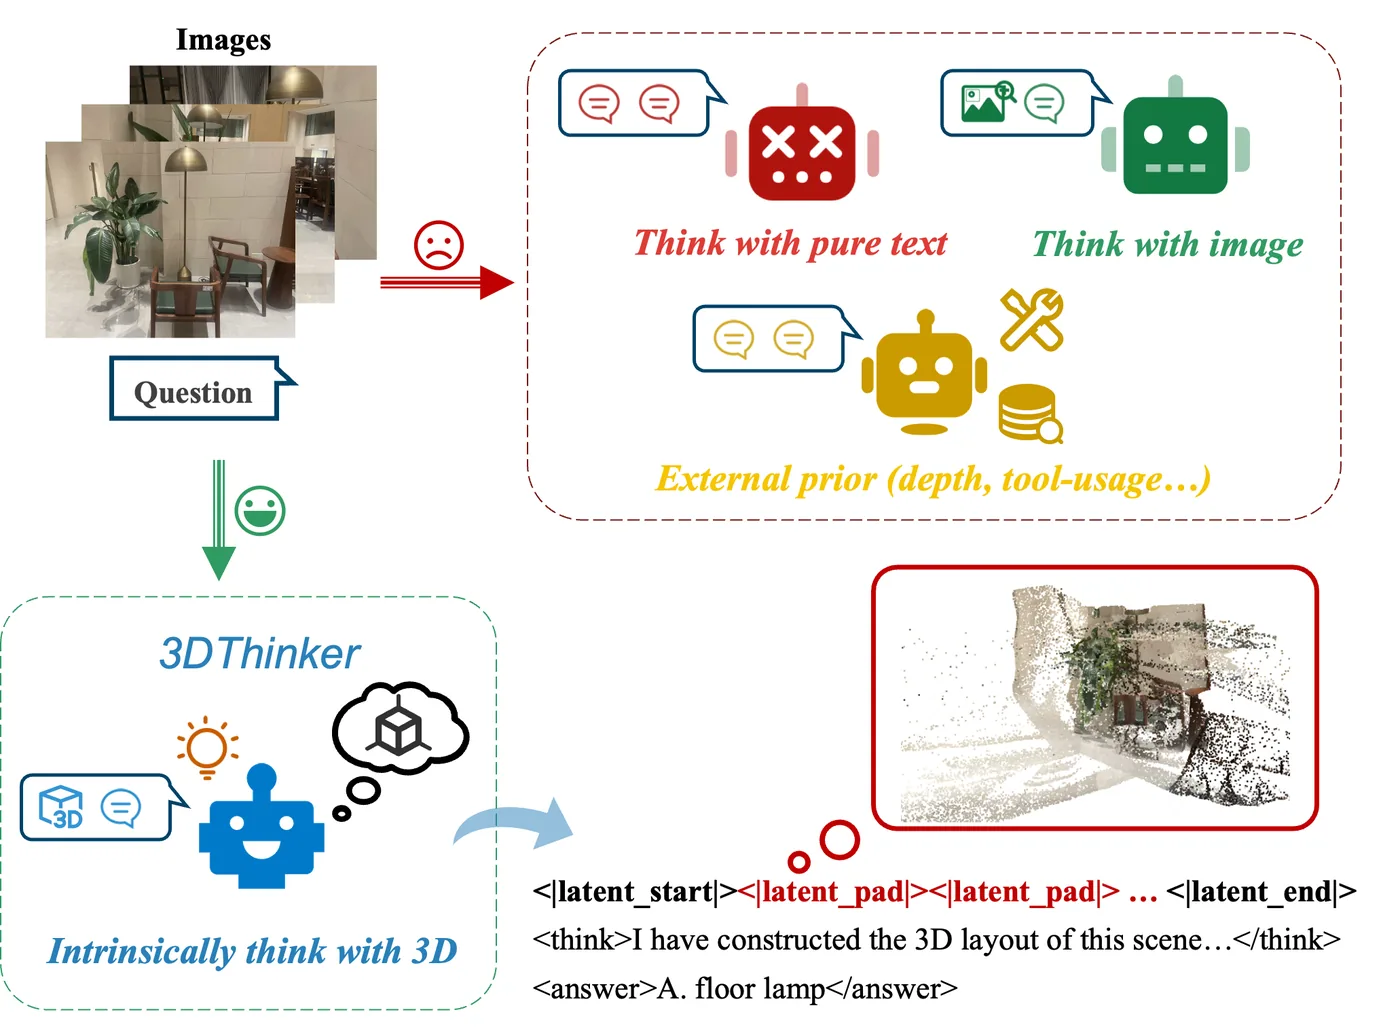
The idea: a 3D latent block inside the reasoning思路:推理中的一段 3D 潜在表示
People asked where something is in a room they glimpsed picture the room and look around in it. 3DThinker gives a vision-language model a place to do the same. Its output is split as o = opre ⊕ t3D ⊕ opost, where t3D is a short run of special tokens standing for the imagined scene. The last-layer hidden states at those positions, Flatent, are what the model “sees” in its mind. They are generated autoregressively like any other token, conditioned on the question, the images and what came before.
人们被问到只匆匆看过一眼的房间里某样东西在哪里时,会在脑中想象出房间,再在里面四处“看看”。3DThinker 给视觉语言模型留出做这件事的位置。它的输出被拆成 o = opre ⊕ t3D ⊕ opost,其中 t3D 是一小段代表想象场景的特殊 token。这些位置最后一层的隐状态 Flatent 就是模型在脑中“看到”的东西。它们和其他 token 一样自回归生成,以问题、图像和此前的输出为条件。
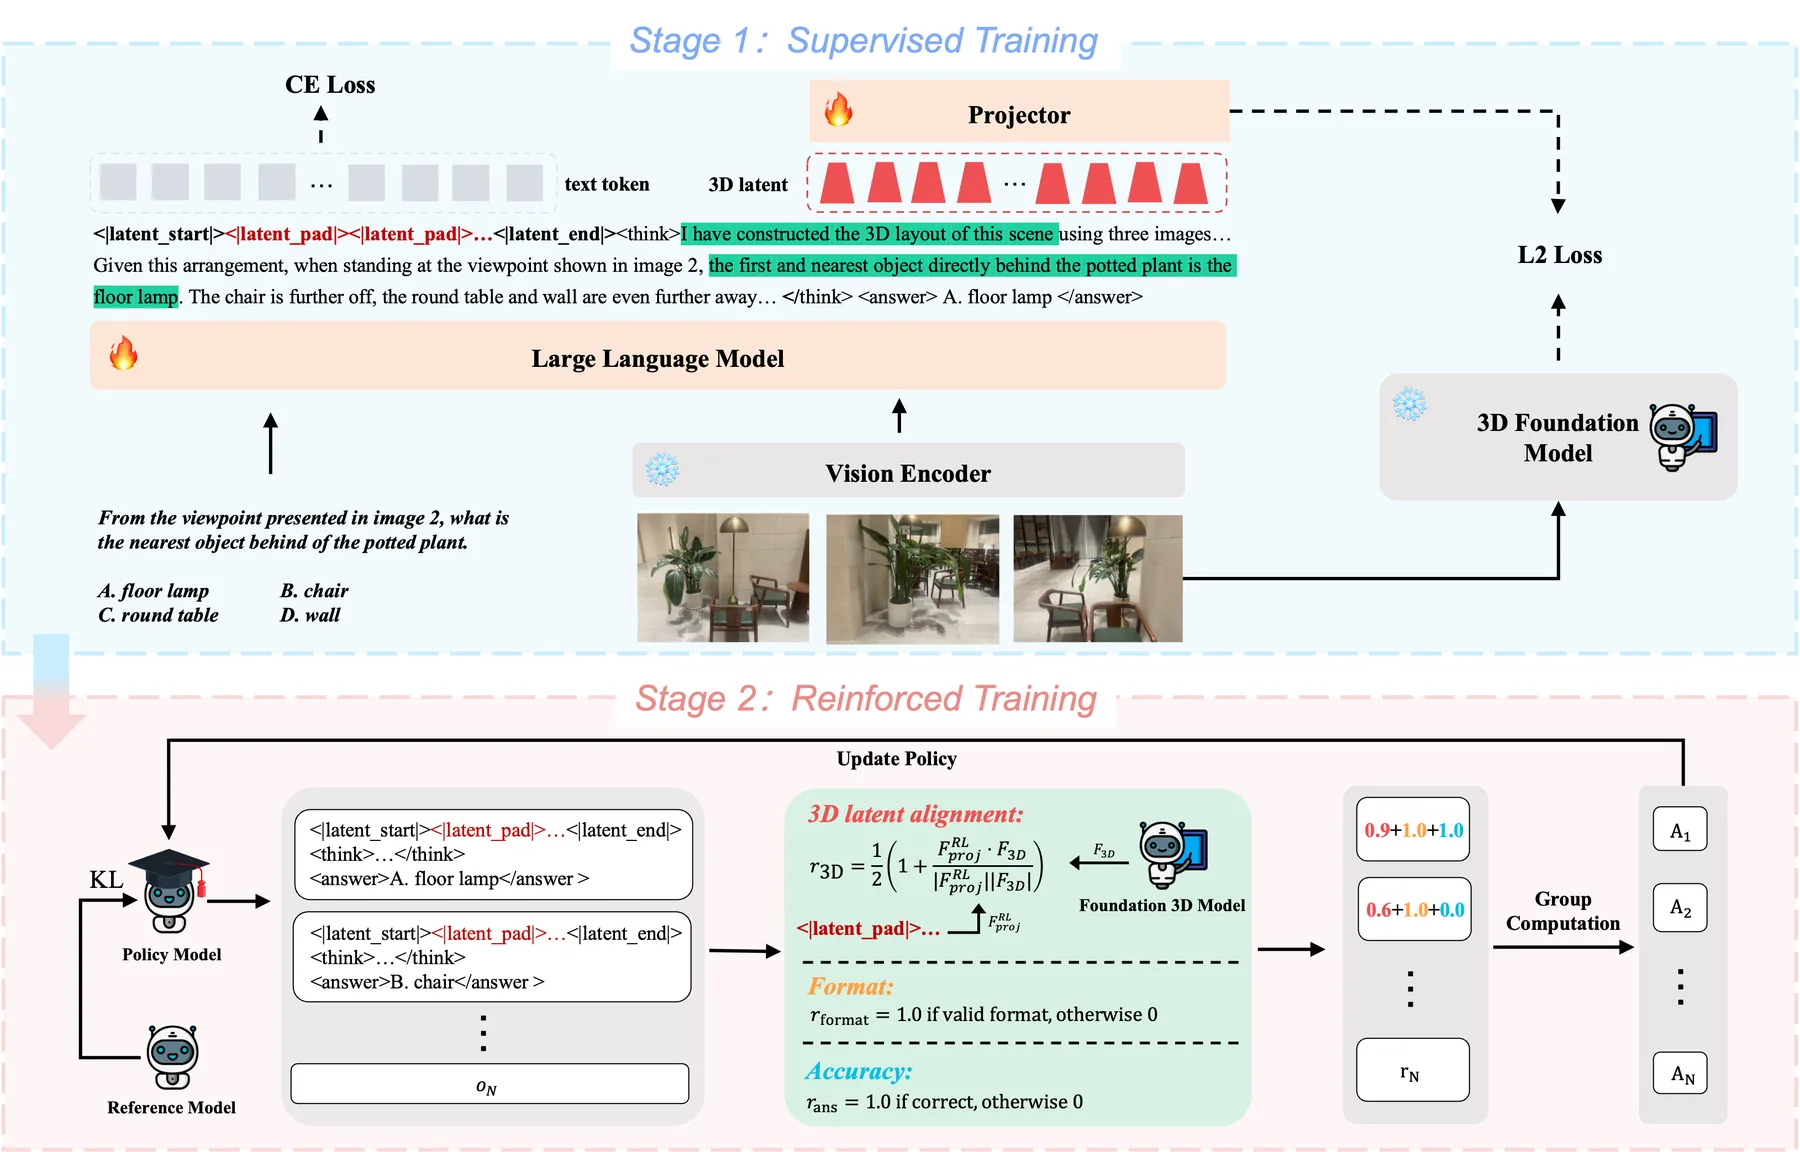
The closest earlier work, Mirage, also continues a reasoning trajectory with latent embeddings, but it supervises them with ground-truth image embeddings and stays within “thinking with images”. 3DThinker supervises its latents with a 3D foundation model instead: VGGT reads the same views during training and supplies the target features, so no 3D data has to be built. Training has two stages (Figure 3). Stage 1 teaches the model to write the latent block and aligns it with VGGT; Stage 2 refines the whole trajectory, latents included, from outcome rewards alone.
最接近的已有工作 Mirage 同样用潜在嵌入延续推理轨迹,但它用真实图像的嵌入作监督,停留在“用图像思考”的范式里。3DThinker 改用 3D 基础模型来监督潜在 token:训练时 VGGT 读取同一组视角并给出目标特征,因此无需构建任何 3D 数据。训练分两个阶段(图 3)。阶段 1 教模型写出潜在 token 段并与 VGGT 对齐;阶段 2 只依靠结果奖励优化包括潜在 token 在内的整条轨迹。
Training data with a 3D placeholder带 3D 占位符的训练数据
A vision-language model only writes text, so it first needs examples of reasoning that contain a 3D step. Given the images, the question and the ground-truth answer of an existing question–answer pair, GPT-4.1 writes the step-by-step reasoning and puts an <output_3D> placeholder at the start, followed by <think>…</think><answer>…</answer>. A trace in the wrong format is regenerated, and a sample that still fails after ten attempts is dropped. GPT-4.1 only places the placeholder; the geometry behind it comes from VGGT. That is what the paper means by annotation-free: no manual geometric labels such as ground-truth point clouds.
视觉语言模型只会写文本,因此先要有包含 3D 步骤的推理示例。对于已有的问答对,GPT-4.1 根据图像、问题和标准答案写出逐步推理,在开头放一个 <output_3D> 占位符,后面接 <think>…</think><answer>…</answer>。格式不对的推理会重新生成,尝试 10 次仍不合格的样本被丢弃。GPT-4.1 只负责放置占位符,占位符背后的几何信息来自 VGGT。论文所说的“无需标注”就是这个意思:不需要真实点云这类人工几何标注。
Two training sets appear in the paper. MindCube-only uses 10,000 MindCube question–image–answer pairs: Stage 1 trains on their generated reasoning, and Stage 2 on the plain question, images and answer, with no annotated cognitive maps at any stage. The large-scale curated set draws on MM-Spatial, SPAR, MindCube and SpatialLadder; Gemini 2.5 Pro rated the data quality and the single- and multi-image shares were balanced, leaving 237K samples. Stage 1 trains on all of it for one epoch, Stage 2 on a 57K subset. Results marked * below use the large-scale set.
论文用到两套训练数据。MindCube-only 取 MindCube 中 10,000 个问题–图像–答案三元组:阶段 1 在生成的推理链上训练,阶段 2 只用问题、图像和答案,各阶段都不用标注的认知地图。大规模精选数据来自 MM-Spatial、SPAR、MindCube 和 SpatialLadder;先由 Gemini 2.5 Pro 评估数据质量,再平衡单图与多图样本的比例,最终保留 237K 条。阶段 1 在全部数据上训练一个 epoch,阶段 2 用其中 57K 条。下文标 * 的结果使用这套大规模数据。
Data pipeline in the repository: CoT generation, cleaning and VGGT features代码仓库中的数据流程:CoT 生成、清洗与 VGGT 特征
The repository builds the MindCube-only set from MindCube’s MindCube_train_raw_qa_qwen_sft.json and its images; data/idx.jsonl lists the 10,000 samples with their indices. The result, data_output3d_begin_10k_resized.jsonl, is also released as the 3DThinker-10K dataset (see Open-source resources).
代码仓库用 MindCube 的 MindCube_train_raw_qa_qwen_sft.json 及其图像构建 MindCube-only 数据;data/idx.jsonl 列出了 10,000 个样本及其编号。最终得到的 data_output3d_begin_10k_resized.jsonl 也作为 3DThinker-10K 数据集发布(见“开源资源”)。
CoT generationCoT 生成
preprocessing/produce_cot.py calls GPT-4.1 with a system prompt (excerpt below) and a user prompt that gives the question and the answer and asks it to “start with the mental 3D scene special token <output_3D> and complete the reasoning chain”. It retries up to ten times until the reply holds exactly one <output_3D>, no </output_3D>, and a <think>…</think> <answer>…</answer> pair.
preprocessing/produce_cot.py 调用 GPT-4.1,使用下面摘录的系统提示词,并在用户提示词中给出问题和答案,要求它“以心理 3D 场景特殊 token <output_3D> 开头,补全推理链”。脚本最多重试 10 次,直到回复中恰好有一个 <output_3D>、没有 </output_3D>,并且包含 <think>…</think> <answer>…</answer>。
You are an advanced AI reasoning assistant with expertise in 3D spatial
understanding. Your task is to complete the intermediate reasoning process
using the provided Question, Images, and Answer. To assist your reasoning,
you should mentally construct a 3D layout of the scene.

Wrap your reasoning process with <think></think> tags and your final result
with <answer></answer> tags. The mental 3D scene you imagine will be
represented by the special token <output_3D>, which should be presented at
the beginning of your response. Only one <output_3D> is allowed, and
</output_3D> should not be included.
# … followed by one worked example
Cleaning and indexing清洗与编号
Three more scripts run in order: clean.py drops entries whose output does not contain exactly one <output_3D> or contains </output_3D>, remove.py drops entries that do not have two or four images, and jsonl_add_idx.py attaches the index that names each sample’s VGGT feature file.
随后依次运行三个脚本:clean.py 删除输出中 <output_3D> 不是恰好一个或含有 </output_3D> 的条目,remove.py 删除图像数量不是 2 张或 4 张的条目,jsonl_add_idx.py 为每条样本加上编号,对应它的 VGGT 特征文件。
python preprocessing/feature/extract_vggt_feature.py   # VGGT features + resized images
python preprocessing/produce_cot.py                    # chain-of-thought data
python preprocessing/clean.py                          # remove non-compliant data
python preprocessing/remove.py                         # filter useless data
python preprocessing/jsonl_add_idx.py                  # match VGGT indices
Each line of data/example.jsonl, the 99-sample example set in the repository, has the fields text_input, image_input (image paths), text_output (the trace beginning with <output_3D>), answer, mindcube_input, mindcube_output and idx.
仓库中的示例数据 data/example.jsonl 共 99 条,每行包含字段 text_input、image_input(图像路径)、text_output(以 <output_3D> 开头的推理链)、answer、mindcube_input、mindcube_output 和 idx。
VGGT feature extractionVGGT 特征提取
preprocessing/feature/extract_vggt_feature.py loads the VGGT-1B weights, resizes each sample’s images (saved to data/resized_images), runs only VGGT’s aggregator and saves its last-layer tokens as data/feature_vggt/{idx}/vggt.npz, one 1374 × 2048 map per view. Training reads these files, so VGGT never runs inside the training loop or at inference.
preprocessing/feature/extract_vggt_feature.py 加载 VGGT-1B 权重,缩放每个样本的图像(保存到 data/resized_images),只运行 VGGT 的聚合器,并把最后一层的 token 保存为 data/feature_vggt/{idx}/vggt.npz,每个视角一张 1374 × 2048 的特征图。训练直接读取这些文件,因此 VGGT 既不在训练循环中运行,也不参与推理。
images = load_and_preprocess_images(new_image_paths)
images = images.to(device, non_blocking=True).to(dtype).unsqueeze(0)
with torch.no_grad():
    with torch.cuda.amp.autocast(enabled=True, dtype=dtype):
        aggregated_tokens_list, ps_idx = model.aggregator(images)
feature = aggregated_tokens_list[-1].cpu().numpy()   # last aggregator layer
np.savez_compressed(save_path, feature=feature, ps_idx=ps_idx_np)
Stage 1: align the imagined scene with VGGT阶段 1:让想象的场景对齐 VGGT
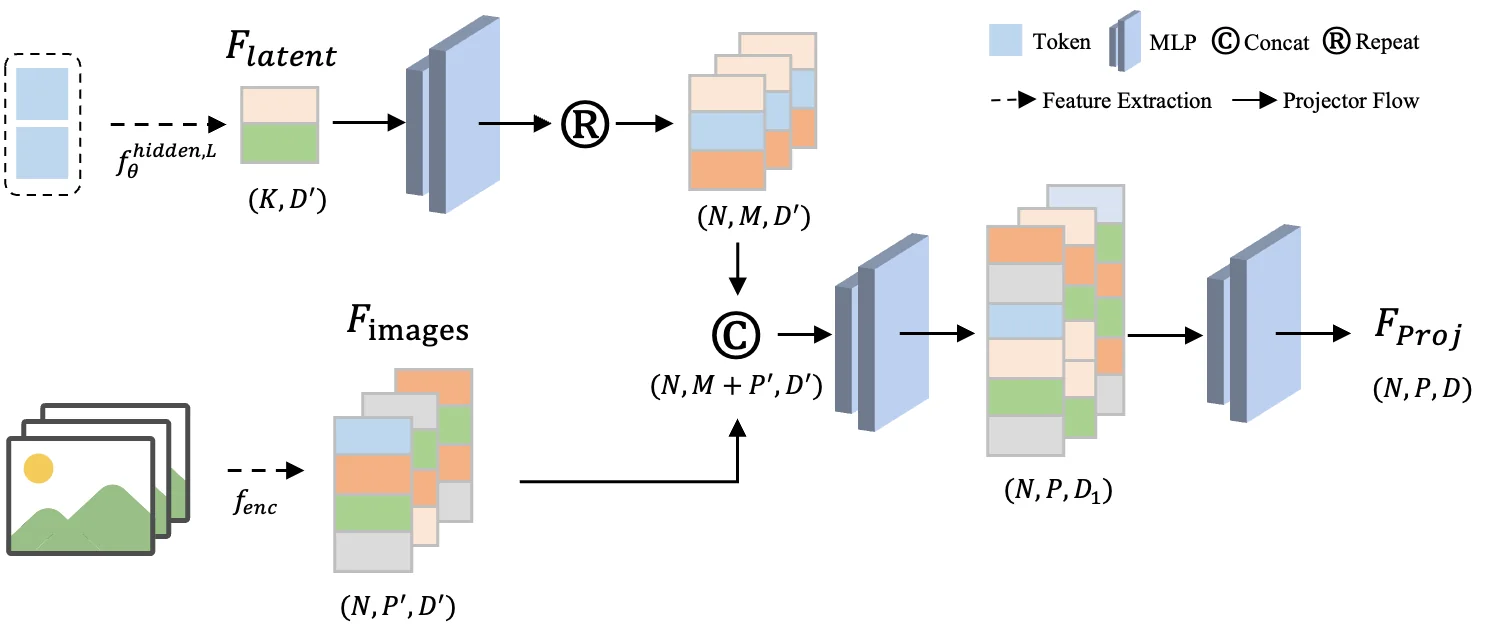
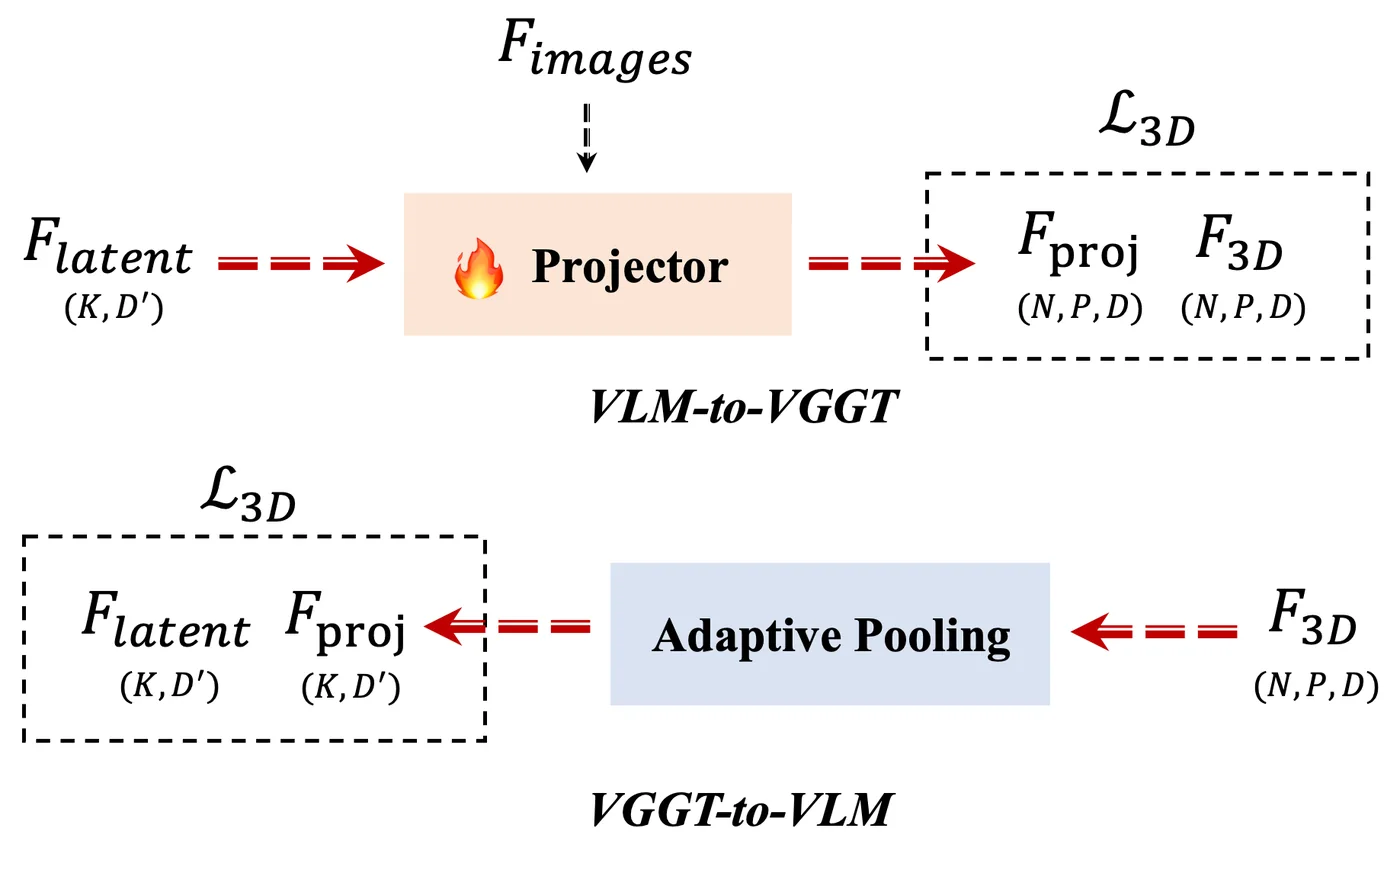
The obvious way to teach 3D reasoning, making the model output point clouds, needs 3D labels and a model that can generate geometry explicitly. Stage 1 distils instead. The last layer of VGGT’s aggregator gives geometry features F3D for the input views; the image encoder gives patch features Fimages. A projector (Figure 4) turns the latent hidden states, together with the patch features, into Fproj of the same shape as F3D, and a Frobenius loss pulls them together. Cross-entropy on the text before and after the latent block keeps the reasoning coherent.
教模型做 3D 推理,最直接的办法是让它输出点云,但这需要 3D 标注,还要求模型能显式生成几何。阶段 1 改用蒸馏。VGGT 聚合器的最后一层为输入视角给出几何特征 F3D,图像编码器给出 patch 特征 Fimages。投影器(图 4)把潜在隐状态与 patch 特征一起转换为与 F3D 同形状的 Fproj,再用 Frobenius 损失拉近两者。潜在 token 段前后的文本仍用交叉熵训练,保证推理通顺。
For the MindCube-only models, Stage 1 uses an MLP depth of 6, a learning rate of 1e-4, twelve latent tokens and ten epochs. In the released code the vision encoder stays frozen while the language model and the projector are trained. The projector maps the VLM’s latents into VGGT’s space rather than VGGT’s features into the VLM’s, so the imagined scene can be decoded back into geometry with VGGT’s own heads (see What 3DThinker’s latents encode below).
对于 MindCube-only 模型,阶段 1 的 MLP 深度为 6,学习率 1e-4,潜在 token 12 个,训练 10 个 epoch。开源代码中视觉编码器保持冻结,训练语言模型和投影器。投影方向是把 VLM 的潜在表示映射到 VGGT 的空间,而不是把 VGGT 的特征压缩到 VLM 的空间,因此想象出的场景可以用 VGGT 自己的预测头解码回几何(见下文“3DThinker 的潜在 token 编码了什么”)。
Special tokens: from <output_3D> to twelve <|latent_pad|>特殊 token:从 <output_3D> 到 12 个 <|latent_pad|>
3dthinker/stage1/src/main.py adds three special tokens to the Qwen2.5-VL tokenizer, <|latent_pad|>, <|latent_start|> and <|latent_end|> (ids 151665, 151666 and 151667 according to the code comments), and resizes the token embeddings. When a batch is built, the <output_3D> placeholder in the assistant turn becomes <|latent_start|><|image_pad|><|latent_end|>, and process_batch then replaces the span between start and end with latent_size copies of <|latent_pad|>. With --latent_size 12 the model therefore learns to write:
3dthinker/stage1/src/main.py 向 Qwen2.5-VL 的分词器加入三个特殊 token:<|latent_pad|>、<|latent_start|> 和 <|latent_end|>(据代码注释,id 分别为 151665、151666、151667),并扩展词嵌入表。构建批次时,助手回复中的 <output_3D> 占位符先被替换为 <|latent_start|><|image_pad|><|latent_end|>,再由 process_batch 把首尾之间的内容替换为 latent_size 个 <|latent_pad|>。设置 --latent_size 12 时,模型学会写出:
<|latent_start|><|latent_pad|> … <|latent_pad|><|latent_end|>   # 12 × <|latent_pad|>
<think> … </think><answer> … </answer>
The paper places the block at the very beginning, before <think>. The ablations below show why: placed between <think> and </think> it breaks the text.
论文把这段 token 放在最前面,即 <think> 之前。下文的消融说明了原因:放在 <think> 与 </think> 之间会破坏文本。
Projector shapes in the released code开源代码中投影器的张量形状
multimodal_projector/mmprojector.py defines the projector, built in main.py as projector(mlp_depth=6, mm_hidden_size=2048, hidden_size=2048, latent_size=12, fusion_input=391, fusion_output=1374). For one sample with N views:
投影器定义在 multimodal_projector/mmprojector.py 中,main.py 以 projector(mlp_depth=6, mm_hidden_size=2048, hidden_size=2048, latent_size=12, fusion_input=391, fusion_output=1374) 构建。对于一个有 N 个视角的样本:
- Inputs: the latent hidden states, 12 × 2048 (2048 is the hidden size of Qwen2.5-VL-3B), and the image tokens as they enter the language model, N × 391 × 2048.
- A two-layer MLP with GELU over the token axis turns the 12 latents into 64 (
prompte_model). - For each view, the 64 latent rows are concatenated with its 391 image tokens (455 tokens), and a six-layer MLP over the token axis maps 455 to 1374 tokens (
fusion_model). - A six-layer MLP over channels maps 2048 to 2048 (
proj_3d_model). - Output Fproj: N × 1374 × 2048, the shape of VGGT’s aggregator tokens for N views: 1 camera token, 4 register tokens and 37 × 37 patch tokens of a 518-pixel image per view, 2048 channels.
- 输入:潜在隐状态 12 × 2048(2048 是 Qwen2.5-VL-3B 的隐藏维度),以及进入语言模型时的图像 token,N × 391 × 2048。
- 沿 token 维度的两层 GELU MLP 把 12 个潜在 token 变为 64 个(
prompte_model)。 - 每个视角把这 64 行与该视角的 391 个图像 token 拼接(共 455 个),再由沿 token 维度的六层 MLP 映射为 1374 个 token(
fusion_model)。 - 沿通道维度的六层 MLP 把 2048 维映射到 2048 维(
proj_3d_model)。 - 输出 Fproj:N × 1374 × 2048,与 VGGT 聚合器在 N 个视角上的 token 形状相同:每个视角 1 个相机 token、4 个寄存器 token 和 518 像素图像的 37 × 37 个 patch token,通道数 2048。
The sizes are hard-coded for the 3B model; a comment in main.py notes the hidden sizes of the 7B (3584) and 72B (5120) models.
这些尺寸是为 3B 模型写死的;main.py 中的注释给出了 7B(3584)和 72B(5120)模型的隐藏维度。
Training loss as implemented代码中实现的训练损失
CustomTrainerStage1.compute_loss in trainer_single.py takes the cross-entropy from the SFT trainer, gathers the last-layer hidden states at the latent positions and the image embeddings, runs the projector, loads the sample’s VGGT features and adds a squared-error term. The weights differ from the paper’s λ3D = 0.1, λtext = 1: the code multiplies the cross-entropy by 0.1 and the squared error, summed over channels and averaged over tokens, by 0.0005.
trainer_single.py 中的 CustomTrainerStage1.compute_loss 先从 SFT 训练器得到交叉熵,再取潜在 token 位置的最后一层隐状态和图像嵌入,送入投影器,读取该样本的 VGGT 特征,加上平方误差项。代码中的权重与论文给出的 λ3D = 0.1、λtext = 1 不同:交叉熵乘以 0.1,平方误差(在通道上求和、在 token 上取平均)乘以 0.0005。
feature_proj = model.projector_model(shift_predict_embeddings, image_embeddings)
data = np.load('../../data/feature_vggt/' + str(idx[0]) + '/vggt.npz')
feature_3d = torch.tensor(data['feature']).to(device=..., dtype=...).squeeze()
feature_sim = ((feature_proj - feature_3d.detach()) ** 2).sum(dim=-1)
sim_loss = feature_sim.mean()*0.0005
loss = 0.1 * ce_loss + sim_loss
Launching Stage 1启动阶段 1 训练
Put the base model under models/ (for example Qwen2.5-VL-3B-Instruct), activate the Stage 1 environment and run cd 3dthinker/stage1 && sh train.sh. The script’s arguments, with the base model path shortened:
把基座模型放到 models/ 下(例如 Qwen2.5-VL-3B-Instruct),激活阶段 1 的环境,运行 cd 3dthinker/stage1 && sh train.sh。脚本参数如下(基座模型路径已缩写):
python src/main.py \
    --model <path>/Qwen2.5-VL-3B-Instruct --epochs 10 \
    --task mindcube \
    --latent_size 12 \
    --per_device_train_batch_size 1 \
    --learning_rate 1e-4 \
    --warmup_steps 10 \
    --weight_decay 0.01 \
    --logging_steps 20 \
    --save_steps 2000 \
    --save_total_limit 1 \
    --stage stage1 \
    --data_path ../../data/example.jsonl \
    --log_file ./log.txt \
    --save_model_path ../../models/3DThinker-S1-Qwen2.5-VL-3B_mlp6_lr1e-4_latent12 \
    --wandb_name 3DThinker-S1-Qwen2.5-VL-3B_mlp6_lr1e-4_latent12
Stage 2: refine the whole trajectory from outcomes阶段 2:仅凭结果优化整条轨迹
After Stage 1 the model writes formatted latent blocks and the projector is trained. Stage 2 uses only outcome signals to improve the sampled trajectories and, with them, the imagined scene. It runs outcome-based GRPO: for each question and its images, the current policy samples N completions (eight in the paper), each completion’s reward is normalised against its group, and the policy maximises the clipped objective with a KL penalty to the reference model. The projector is frozen in this stage, and VGGT’s features still constrain the latents through a reward rather than a loss.
阶段 1 之后,模型已经能写出格式正确的潜在 token 段,投影器也训练好了。阶段 2 只用结果信号来改进采样轨迹,并随之改进想象出的场景。它采用基于结果的 GRPO:对每个问题及其图像,当前策略采样 N 条回答(论文中为 8 条),每条回答的奖励在组内归一化,策略最大化带截断的目标函数,并对参考模型施加 KL 惩罚。这一阶段投影器冻结,VGGT 的特征不再作为损失,而是通过奖励继续约束潜在 token。
Three rewards are summed with weight 1 each. The 3D reward r3D runs each rollout’s latent hidden states through the frozen projector and compares the result with VGGT’s features by cosine similarity, mapped to [0, 1]. The format reward rformat is 1.0 when the output follows …<|latent_start|><|latent_pad|>…<|latent_end|>…<think>…</think><answer>…</answer>, and the answer reward rans is 1 when the chosen option matches the ground truth and 0 otherwise. Stage 2 uses a learning rate of 1e-5 and eight rollouts per question.
三项奖励各以权重 1 相加。3D 奖励 r3D 把每条轨迹的潜在隐状态送入冻结的投影器,与 VGGT 特征计算余弦相似度,并映射到 [0, 1]。格式奖励 rformat 在输出符合 …<|latent_start|><|latent_pad|>…<|latent_end|>…<think>…</think><answer>…</answer> 时为 1.0;答案奖励 rans 在所选选项与标准答案一致时为 1,否则为 0。阶段 2 的学习率为 1e-5,每个问题采样 8 条轨迹。
Reward functions as implemented代码中实现的奖励函数
The rewards live in vlm_modules/qwen_module.py of the Stage 2 code (a fork of VLM-R1’s open-r1-multimodal) and are switched on with --reward_funcs format response latent_sim. The trainer sums them per rollout (rewards_per_func.sum(dim=1)) and normalises within each group of num_generations with δ = 1e-4.
奖励函数位于阶段 2 代码(基于 VLM-R1 的 open-r1-multimodal 修改)的 vlm_modules/qwen_module.py 中,通过 --reward_funcs format response latent_sim 启用。训练器对每条轨迹把它们相加(rewards_per_func.sum(dim=1)),再在每组 num_generations 条轨迹内归一化,δ = 1e-4。
- format (
format_reward): 1.0 if the completion matches.*?<\|latent_start\|>.*?<think>.*?</think>\s*<answer>.*?</answer>, else 0.0. The pattern checks the start token, not the number of pads. - response (
response_text_reward): the text inside <answer> goes throughextract_option, a cascade of regular expressions for an option letter A–E; 1.0 if a letter is found and equals the ground truth’s letter, else 0.0. - latent_sim (
sim_reward): the frozen projector, loaded from the Stage 1 checkpoint, maps the rollout’s latent embeddings and image embeddings to VGGT’s space; both sides are L2-normalised, the mean cosine similarity withdata/feature_vggt/{idx}/vggt.npzis taken, and the reward is (cos + 1) / 2.
- format(
format_reward):回答匹配.*?<\|latent_start\|>.*?<think>.*?</think>\s*<answer>.*?</answer>时为 1.0,否则为 0.0。这个模式只检查起始 token,不检查 pad 的个数。 - response(
response_text_reward):<answer> 内的文本交给extract_option,用一串按优先级排列的正则表达式提取选项字母 A–E;提取到字母且与标准答案的字母一致时为 1.0,否则为 0.0。 - latent_sim(
sim_reward):从阶段 1 检查点加载的冻结投影器把该轨迹的潜在嵌入和图像嵌入映射到 VGGT 空间;两侧都做 L2 归一化后,与data/feature_vggt/{idx}/vggt.npz求平均余弦相似度,奖励为 (cos + 1) / 2。
decoder_feature = projector_model(extracted_emb.to(target_dtype).to("cuda:0"),
                                  image_embeddings.to(target_dtype).to("cuda:0"))
decoder_feature_norm = decoder_feature / decoder_feature.norm(dim=-1, p=2, keepdim=True)
data = np.load('../../data/feature_vggt/' + str(idx) + '/vggt.npz')
feature_3d = torch.tensor(data['feature']).to(...).squeeze()
feature_3d_norm = feature_3d / feature_3d.norm(dim=-1, p=2, keepdim=True)
cos_sim = torch.nn.functional.cosine_similarity(decoder_feature_norm, feature_3d_norm).mean()
reward = (cos_sim + 1) / 2
Launching Stage 2 and merging the LoRA weights启动阶段 2 训练并合并 LoRA 权重
The released script trains LoRA adapters (rank 64, α = 128, dropout 0.05) on the Stage 1 checkpoint with the vision modules frozen, eight GPUs, vLLM rollouts and DeepSpeed ZeRO-3. The main arguments of 3dthinker/stage2/run_scripts/train.sh:
开源脚本在阶段 1 检查点上训练 LoRA 适配器(秩 64、α = 128、dropout 0.05),视觉模块冻结,使用 8 张 GPU、vLLM 采样和 DeepSpeed ZeRO-3。3dthinker/stage2/run_scripts/train.sh 的主要参数:
model_path="../../models/3DThinker-S1-Qwen2.5-VL-3B_mlp6_lr1e-4_latent12"
export EXP_NAME="3DThinker-S1+S2-Qwen2.5-VL-3B_lr1e-5_gen8"
torchrun --nproc_per_node="8" --nnodes="1" --node_rank="0" \
    --master_addr="127.0.0.1" --master_port="12346" \
  src/open_r1/grpo_jsonl.py \
    --use_vllm True \
    --model_name_or_path $model_path \
    --is_reward_customized_from_vlm_module True \
    --task_type rec \
    --per_device_train_batch_size 1 \
    --gradient_accumulation_steps 2 \
    --num_train_epochs 1 \
    --num_generations 8 \
    --max_completion_length 2048 \
    --reward_funcs format response latent_sim \
    --beta 0.04 \
    --learning_rate 1e-5 \
    --use_peft true --lora_r 64 --lora_alpha 128 --lora_dropout 0.05 \
    --freeze_vision_modules true \
    --deepspeed local_scripts/zero3.json --bf16
After training, the README merges the adapters with LLaMA-Factory in the SFT environment: conda activate SFT && llamafactory-cli export merge.yaml. The repository does not ship a merge.yaml; write one that names the Stage 1 model, the Stage 2 adapter and an export directory.
训练结束后,README 在 SFT 环境中用 LLaMA-Factory 合并适配器:conda activate SFT && llamafactory-cli export merge.yaml。仓库没有提供 merge.yaml,需要自己写一个,指明阶段 1 模型、阶段 2 适配器和导出目录。
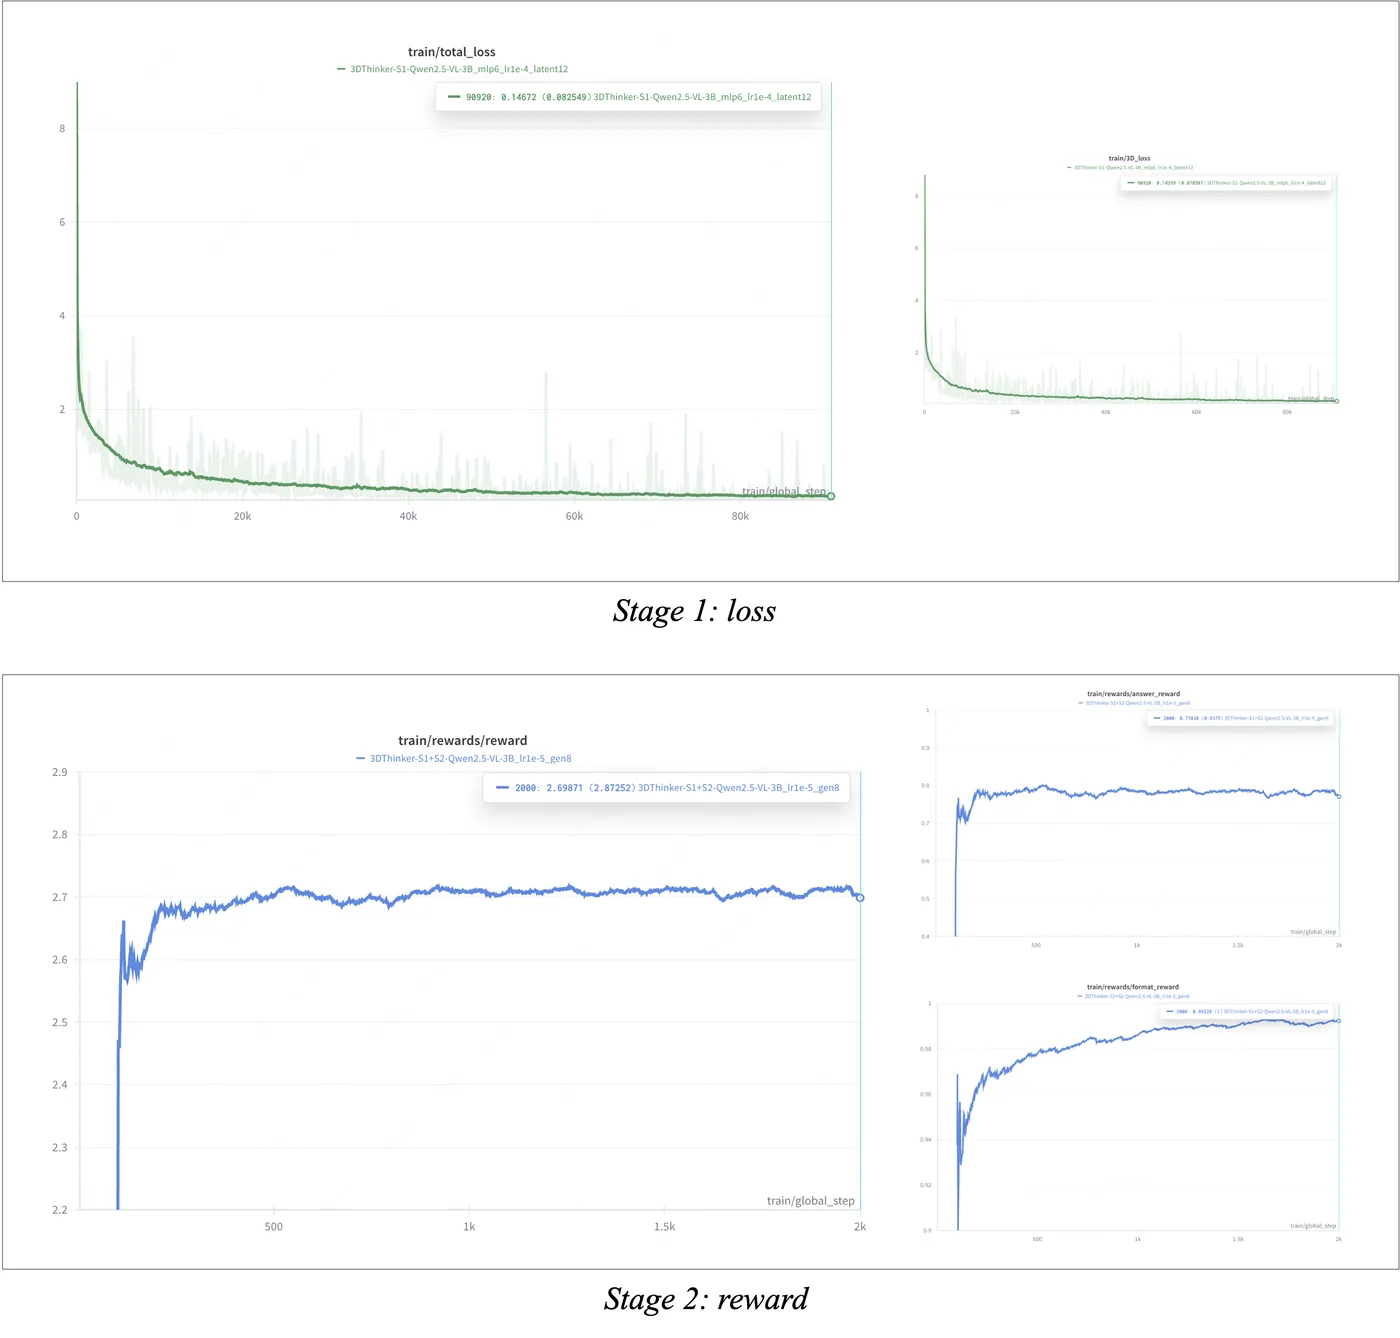
Training curves and cost (Figure 5)训练曲线与开销(图 5)
On MindCube-only, the Stage 1 loss converges after about 20k steps at around 0.15; the Stage 2 reward settles much sooner, after about 500 steps at around 2.7 out of 3. The format and answer rewards both dip early, which the paper attributes to exploration at the start of RL, then rise steadily. For Qwen2.5-VL-3B on a single H200 with batch size 1, Stage 1 takes 21.84 h and Stage 2 12.85 h to converge.
在 MindCube-only 数据上,阶段 1 的损失约在 2 万步后收敛到 0.15 左右;阶段 2 的奖励收敛得快得多,约 500 步后稳定在 2.7 左右(满分 3)。格式奖励和答案奖励在早期都有短暂下降,论文认为这是强化学习初期的探索所致,之后稳步上升。对于 Qwen2.5-VL-3B,在单张 H200、批大小为 1 时,阶段 1 和阶段 2 分别需要 21.84 小时和 12.85 小时收敛。
4DThinker: from a still scene to a moving one4DThinker:从静止的场景到运动的场景
3DThinker imagines a static scene from a few photos. Many questions about the physical world are about change instead: how the camera moved, which way a car is heading, whether a person slows down. Answering them from a monocular video means separating the camera’s ego-motion from the motion of objects, which matters for driving and robotics, and recent benchmarks show that even the strongest vision-language models fail at basic cases. Two kinds of fixes exist. One writes the spatial-temporal reasoning out as text, which is verbose and imprecise for complex motion; the other adds external modules, such as 3D foundation models that inject geometric priors or mask decoders for grounding, which makes inference heavier and leaves the skill outside the model. Latent reasoning methods, 3DThinker included, have so far covered static scenes and relied on annotated reference images or distilled foundation models for supervision, which is hard to scale to video.
3DThinker 根据几张照片想象静态场景。但关于物理世界的很多问题问的是变化:相机怎么移动、汽车往哪个方向开、一个人是否在减速。要从单目视频回答这些问题,需要把相机自身的运动和物体的运动区分开,这对自动驾驶和机器人至关重要;近期的基准显示,即使最强的视觉语言模型也会在基本情形上出错。现有的改进有两类:一类把时空推理全部写成文字,面对复杂运动时既冗长又不精确;另一类增加外部模块,例如注入几何先验的 3D 基础模型或用于定位的掩码解码器,这会让推理更重,能力也不在模型自身。包括 3DThinker 在内的潜在推理方法目前只覆盖静态场景,并依赖带标注的参考图像或蒸馏的基础模型作为监督,很难扩展到视频。
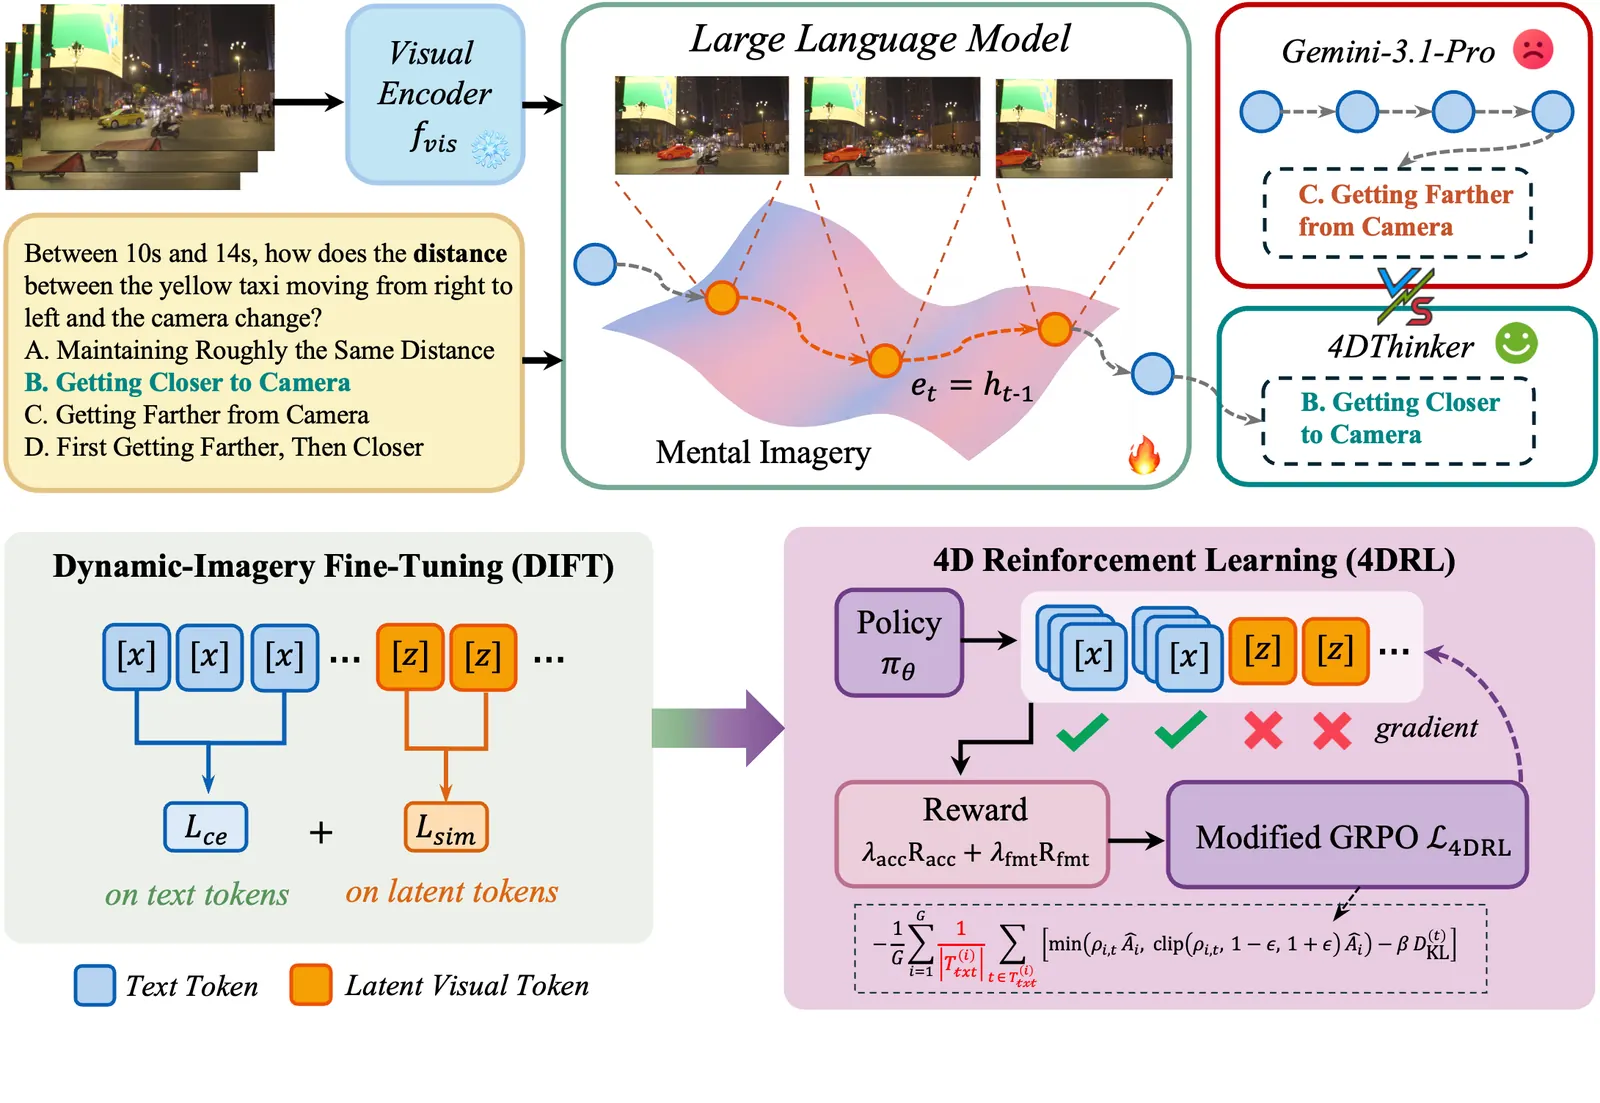
4DThinker sets three goals: extend latent visual reasoning to how a scene evolves (imagery-dynamic), keep the skill inside the model with no external geometric module (model-intrinsic), and scale without manual annotation (data-scalable). It takes its cue from how people follow motion: they anchor on static landmarks to judge their own movement and track the trajectories of moving things. 4DThinker highlights such landmarks with mask overlays and treats the highlighted frames as the imagery the model learns to picture in its own hidden space (Figure 6).
4DThinker 设定了三个目标:把潜在视觉推理扩展到场景随时间的演变(动态想象),让能力留在模型内部、不借助外部几何模块(模型内生),并且无需人工标注就能扩展(数据可扩展)。它借鉴了人类追踪运动的方式:以静止的地标为参照判断自身的移动,同时跟踪运动物体的轨迹。4DThinker 用掩码叠加图突出这些地标,并把这些高亮的帧当作模型要在自身隐空间中学会想象的画面(图 6)。
Input: frames of a monocular video, sampled once per second, and a question about motion.输入:单目视频按每秒一帧采样的画面,以及一个关于运动的问题。 Imagery: the moving object tinted in its mask; the reasoning holds one block of four latent tokens per overlay.想象图:按掩码给运动物体染色;推理中每张叠加图对应一段 4 个潜在 token。 DIFT: the frozen vision encoder turns each overlay into four targets, and the previous hidden state learns to predict each one.DIFT:冻结的视觉编码器把每张叠加图变成 4 个目标,由上一位置的隐状态学习预测。 At inference each latent feeds the next; 4DRL rewards the answer and format, with gradients on text tokens only.推理时每个潜在 token 接着喂给下一个;4DRL 奖励答案与格式,梯度只作用于文本 token。
Table 1 lists what changes from 3D to 4D. The biggest change is the latent target. 3DThinker aligns its latents with an external 3D teacher through a trained projector; 4DThinker uses the base model’s own frozen vision encoder, applied to the overlay frames, so no other model is distilled and no projector is needed. The imagery also moves inside the reasoning, one block per moment in time, and the reinforcement stage stops pushing gradients through the latent positions (Figure 7).
表 1 列出了从 3D 到 4D 的变化。最大的变化是潜在 token 的目标:3DThinker 通过训练好的投影器把潜在 token 对齐到外部的 3D 教师模型;4DThinker 则把基座模型自己冻结的视觉编码器作用在叠加图上,不再蒸馏其他模型,也不需要投影器。想象图也移到了推理文本内部,每个时刻一段;强化学习阶段则不再让梯度经过潜在位置(图 7)。
Table 1What changes from 3DThinker to 4DThinker, from the two papers and their code. Each column describes its paper’s main setup.表 13DThinker 与 4DThinker 的差异,依据两篇论文及其代码整理。每列描述对应论文的主要设置。
| 3DThinker | 4DThinker | |
|---|---|---|
| Input输入 | A few views of a static scene静态场景的几个视角 | A monocular video, 1 frame per second单目视频,每秒一帧 |
| What is imagined想象的内容 | The 3D scene三维场景 | The attended object over time, as mask-overlay frames被关注物体随时间的变化(掩码叠加帧) |
| Latent target潜在 token 的目标 | VGGT aggregator features, through a trained projectorVGGT 聚合器特征,经训练好的投影器对齐 | The model’s own frozen vision-encoder embeddings of the overlays, mean-pooled模型自身冻结的视觉编码器对叠加图的嵌入,分组平均 |
| Latent blocks潜在 token 段 | One block of 12 tokens, before <think>一段 12 个 token,位于 <think> 之前 | One block of 4 tokens per overlay, inside <think>每张叠加图一段 4 个 token,位于 <think> 内部 |
| Stage 1 loss阶段 1 损失 | Cross-entropy + ‖Fproj − F3D‖²交叉熵 + ‖Fproj − F3D‖² | DIFT: 0.1 · cross-entropy + 1.0 · (1 − cos)DIFT:0.1 · 交叉熵 + 1.0 ·(1 − cos) |
| Stage 2 rewards阶段 2 奖励 | r3D + rformat + rans, weight 1 eachr3D + rformat + rans,权重均为 1 | 4DRL: 1.0 · Racc + 0.2 · Rfmt; no latent reward4DRL:1.0 · Racc + 0.2 · Rfmt;无潜在奖励 |
| Gradient at latent positions in RL强化学习中潜在位置的梯度 | Yes: the reward is spread over every token有:奖励分配到每个 token | No: the loss covers text positions only无:损失只计算文本位置 |
| Training data训练数据 | 10K MindCube or 237K curated samples; traces by GPT-4.110K MindCube 或 237K 精选样本;推理链由 GPT-4.1 生成 | ~38K from SpatialVID (Gemini-3-pro, SAM3); ~37K DSR-Train for RL约 38K 条来自 SpatialVID(Gemini-3-pro、SAM3);强化学习用约 37K 条 DSR-Train |
| Main benchmarks主要基准 | MindCube-Tiny, Ego3D-Bench and six moreMindCube-Tiny、Ego3D-Bench 及另外六个 | DSR-Bench, Dyn-BenchDSR-Bench、Dyn-Bench |
4D reasoning data from raw video, without labels无需标注、直接从原始视频生成 4D 推理数据
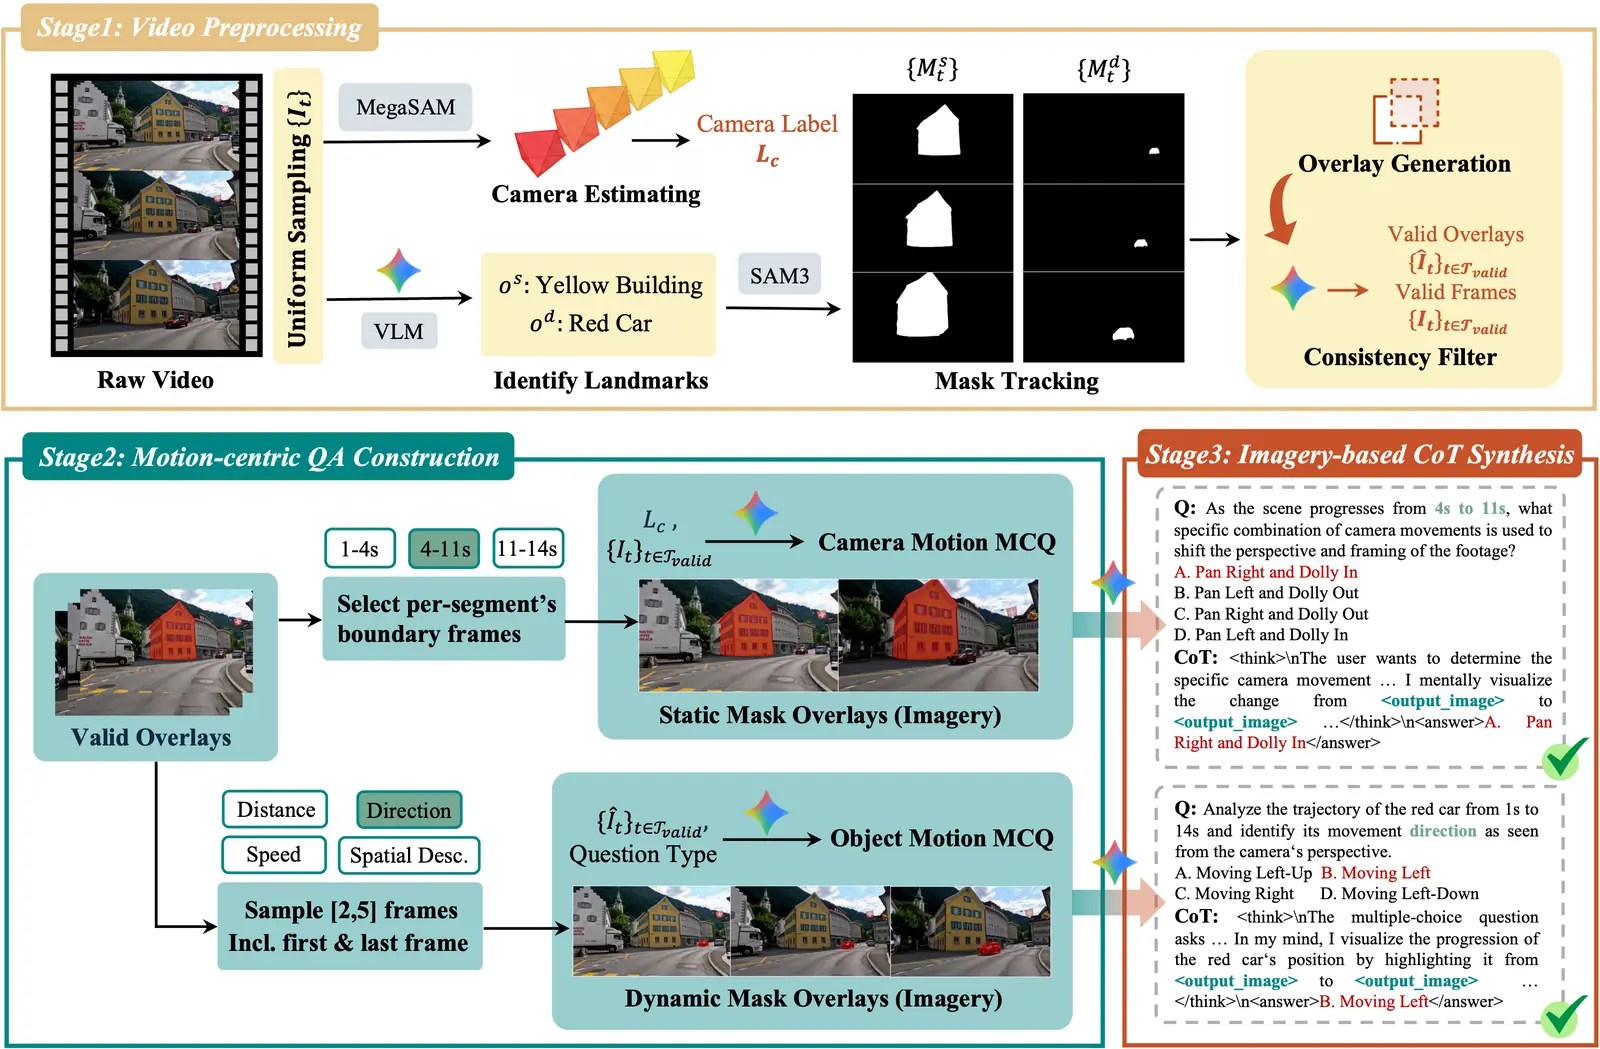
Hand-labelling spatial-temporal data is expensive and does not scale, and 4DThinker also needs reasoning traces that contain imagery. Its pipeline builds both from SpatialVID, a collection of 2.7M clips (7,089 hours) whose camera poses were estimated automatically by MegaSaM; nothing in it needs human annotation (Figure 8). Frames are sampled once per second. Gemini-3-pro picks, by fixed rules, one static object (say, a red building) and one moving object (a person on a blue bike) that persist through the video. SAM3 tracks each to give consistent masks, and each frame gets a mask overlay that tints the object, Ît = (1 − αMt) ⊙ It + αMt ⊙ c, with α = 0.6 and red as c. Gemini then cross-checks the overlays and keeps only those whose object identity stays consistent.
人工标注时空数据成本高、无法扩展,而 4DThinker 还需要包含想象图的推理链。它的数据流程从 SpatialVID 同时构造这两者:SpatialVID 有 270 万段视频(7,089 小时),相机位姿由 MegaSaM 自动估计,整个流程不需要人工标注(图 8)。视频按每秒一帧采样。Gemini-3-pro 按固定规则选出一个贯穿视频的静止物体(例如一栋红色建筑)和一个运动物体(例如骑蓝色自行车的人)。SAM3 逐帧跟踪,得到一致的掩码,每帧再生成一张给物体染色的叠加图:Ît = (1 − αMt) ⊙ It + αMt ⊙ c,其中 α = 0.6,c 为红色。随后 Gemini 交叉核对这些叠加图,只保留物体身份前后一致的帧。
The data is split along two axes. For camera motion, SpatialVID’s per-segment labels of 12 movement types cut the video into segments; Gemini turns a segment’s label into a multiple-choice question, and the imagery is the static object’s overlay at the segment’s first and last frames. A static object does not move, so its apparent shift in the image is caused entirely by the camera. For object motion, questions ask about direction, distance to the camera, speed changes, and direction with a bounding box; Gemini works out the answer by analysing the moving object’s overlays, and the imagery is 2 to 5 of them, always including the first and last frames of the motion. Gemini finally writes the reasoning in the form <think>…<imagery>…<imagery>…</think><answer>…</answer>, and a validator checks the tags, the placeholder count and the answer. This yields about 38K samples for supervised training; the reinforcement stage uses DSR-Train, about 37K question–answer pairs on compound camera and object motion, without reasoning traces.
数据沿两个轴构造。相机运动:SpatialVID 为每个片段给出 12 种运动类型之一的标签,据此把视频切成若干片段;Gemini 把片段的标签改写成选择题,想象图是静止物体在片段首尾两帧的叠加图。静止物体本身不动,它在画面中的位移完全由相机运动造成。物体运动:问题涉及方向、与相机的距离、速度变化,以及带边界框的方向描述;Gemini 通过分析运动物体的叠加图得出答案,想象图取其中 2 到 5 张,且必须包含运动区间的首帧和末帧。最后由 Gemini 写出形如 <think>…<imagery>…<imagery>…</think><answer>…</answer> 的推理,并由校验器检查标签、占位符数量和答案。这样得到约 38K 条监督训练样本;强化学习阶段使用 DSR-Train,约 37K 个关于相机与物体复合运动的问答对,不含推理链。
Question types and answer choices (Tables 2, 3)题型与答案选项(表 2、表 3)
Every generated question has four options: the ground truth and three distractors, drawn preferentially from related motion types so that the question cannot be guessed trivially.
生成的每道题都有四个选项:标准答案加三个干扰项,干扰项优先从语义相近的运动类型中选取,避免题目被轻易猜中。
Table 2Question types in the 4DThinker data pipeline, from the 4DThinker paper’s appendix.表 24DThinker 数据流程中的题型,取自 4DThinker 论文附录。
| Category类别 | Type题型 | Target object目标物体 | Asks考察内容 |
|---|---|---|---|
| Camera motion相机运动 | Direction方向 | Static object静止物体 | How the camera moves相机如何运动 |
| Object motion物体运动 | Direction方向 | Dynamic object运动物体 | Motion direction as seen from the camera从相机视角看的运动方向 |
| Object motion物体运动 | BBox-grounded边界框定位 | Dynamic object运动物体 | Direction, with the object given by a bounding box以边界框指定物体,判断其方向 |
| Object motion物体运动 | Distance距离 | Dynamic object运动物体 | How the object’s distance to the camera changes物体与相机的距离如何变化 |
| Object motion物体运动 | Speed速度 | Dynamic object运动物体 | How the object’s speed varies over time物体速度随时间如何变化 |
Table 3Answer choices for each question type, from the 4DThinker paper’s appendix; each question shows four of them.表 3各题型的答案选项,取自 4DThinker 论文附录;每道题从中给出四个选项。
| Type题型 | Answer choices答案选项 |
|---|---|
| Camera direction相机方向 | Move Forward, Move Backward, Move Left, Move Right, Move Up, Move Down, Pan Left, Pan Right, Tilt Up, Tilt Down, Roll Clockwise, Roll Counter-clockwise前进、后退、左移、右移、上升、下降、左摇、右摇、上仰、下俯、顺时针滚转、逆时针滚转 |
| Object direction物体方向 | Moving Left, Right, Up, Down, Left-Up, Left-Down, Right-Up, Right-Down, Toward Camera, Away from Camera, Stationary向左、向右、向上、向下、左上、左下、右上、右下、靠近相机、远离相机、静止 |
| Object distance物体距离 | Moving Toward Camera, Moving Away from Camera, Maintaining Roughly the Same Distance靠近相机、远离相机、距离大致不变 |
| Object speed物体速度 | Speeding Up, Slowing Down, Maintaining a Constant Speed, First Speeding Up Then Slowing Down, First Slowing Down Then Speeding Up, Moving at Varying Speeds加速、减速、匀速、先加速后减速、先减速后加速、速度多变 |
Data pipeline in the repository代码仓库中的数据流程
The preprocess/ directory runs the pipeline from SpatialVID videos, annotations and metadata, with a SAM3 checkpoint at preprocess/sam3/models/sam3.pt and an OpenAI-compatible API for the Gemini calls. In the released data the imagery placeholder is written <output_image> rather than the paper’s <imagery>, and the latent block uses the same <|latent_start|>, <|latent_pad|>, <|latent_end|> tokens as 3DThinker (the paper writes <lat_s> and <lat_e>).
preprocess/ 目录从 SpatialVID 的视频、标注与元数据出发运行整个流程,需要放在 preprocess/sam3/models/sam3.pt 的 SAM3 检查点,以及一个兼容 OpenAI 接口、用于调用 Gemini 的 API。开源数据中的想象图占位符写作 <output_image>,而不是论文中的 <imagery>;潜在 token 段沿用与 3DThinker 相同的 <|latent_start|>、<|latent_pad|>、<|latent_end|>(论文写作 <lat_s> 和 <lat_e>)。
cd preprocess
export OPENAI_API_KEY=your_api_key
export OPENAI_BASE_URL=https://api.openai.com/v1
export DATA_BASE_DIR=/path/to/your/data
bash run.sh                     # frames + SAM3 masks + object identification
python merge_jsonl.py
python generate_camera_qa.py    # camera motion questions + CoT
python generate_dynamic_qa.py   # object motion questions + CoT
python convert_format.py ./camera_data_qa_all.jsonl ./camera_qa_converted.jsonl
python convert_format.py ./dynamic_data_qa_all.jsonl ./dynamic_qa_converted.jsonl
python check_output_image.py ./camera_qa_converted.jsonl
python check_output_image.py ./dynamic_qa_converted.jsonl
DIFT and 4DRL: learning to think with 4DDIFT 与 4DRL:学会用 4D 思考
Each overlay becomes a short run of latent visual tokens. The base model’s vision encoder fvis turns the overlay into L patch embeddings of dimension D; the sequence is split into K equal parts and each part is averaged, giving K latent tokens z(1)…z(K), with K = 4. Every imagery placeholder in the reasoning is replaced by a latent block, a start token, the K latent vectors and an end token, so training sequences interleave discrete text with continuous embeddings, and the model reasons through the imagery without leaving autoregressive generation.
每张叠加图都会变成一小段潜在视觉 token。基座模型的视觉编码器 fvis 把叠加图编码为 L 个 D 维 patch 嵌入;把这个序列等分成 K 份、每份取平均,得到 K 个潜在 token z(1)…z(K),K = 4。推理中的每个想象图占位符都替换为一段潜在 token:起始 token、K 个潜在向量和结束 token。这样训练序列中离散的文本与连续的嵌入交错出现,模型无需离开自回归生成就能借助想象图推理。
Dynamic-imagery fine-tuning (DIFT). The video frames enter as visual tokens, followed by the question and the reasoning with its latent blocks. The vision encoder is frozen, so the targets stay in a fixed embedding space. Cross-entropy trains the text positions; at the latent positions, a next-embedding objective asks the hidden state before each position, ht−1, to point in the direction of the target zt. At inference this becomes a recurrent loop: inside a latent block the model’s input embedding is its own previous hidden state, so each step of imagined motion feeds the next, and no overlay is ever shown.
动态想象微调(DIFT)。 视频帧作为视觉 token 输入,后接问题和带潜在 token 段的推理。视觉编码器保持冻结,使目标始终处在固定的嵌入空间中。交叉熵训练文本位置;在潜在位置上,“下一嵌入预测”目标要求每个位置之前的隐状态 ht−1 指向目标 zt 的方向。推理时这变成一个循环:在潜在 token 段内,模型的输入嵌入就是它自己上一位置的隐状态,想象中的每一步运动都传给下一步,整个过程不需要任何叠加图。
4D reinforcement learning (4DRL). DIFT only sees one kind of motion per sample, so 4DRL trains on DSR-Train’s compound motions with a modified GRPO. For each question the policy samples G = 8 answers, each scored by R = λaccRacc + λfmtRfmt: 1 for the correct option and 1 for the think-with-4D format, weighted 1.0 and 0.2. Advantages are normalised within the group, and the clipped objective is regularised by a KL term to the frozen DIFT model. The change from standard GRPO is that the loss runs only over text positions: at latent positions the input is a continuous hidden state, not a sampled token, so its log-probability does not describe what happened, and including it adds noisy gradients. Unlike 3DThinker’s Stage 2 there is no reward on the latents.
4D 强化学习(4DRL)。 DIFT 的每条样本只涉及一类运动,因此 4DRL 用改进的 GRPO 在 DSR-Train 的复合运动上训练。对每个问题,策略采样 G = 8 个回答,每个回答的得分为 R = λaccRacc + λfmtRfmt:选项正确得 1,符合“用 4D 思考”的格式得 1,权重分别为 1.0 和 0.2。优势在组内归一化,带截断的目标函数再以对冻结 DIFT 模型的 KL 项正则。与标准 GRPO 的区别在于损失只计算文本位置:潜在位置的输入是连续的隐状态,而不是采样出的 token,它的对数概率并不对应实际发生的事情,计入只会带来噪声梯度。与 3DThinker 的阶段 2 不同,这里没有针对潜在 token 的奖励。
Implementation details, paper and code实现细节:论文与代码
For Qwen2.5-VL-3B, DIFT trains one epoch with batch size 1, AdamW at a learning rate of 1e-5, K = 4, λce = 0.1 and λsim = 1.0, on videos sampled at 1 FPS, on 8 H200 GPUs with DeepSpeed ZeRO-2. 4DRL uses G = 8, λacc = 1.0, λfmt = 0.2, a learning rate of 1e-6, completions of up to 8,192 tokens, β = 0.01, batch size 8 and 2 gradient-accumulation steps. Settings vary somewhat across base models, and the largest (such as InternVL3.5-38B) used up to 64 H200 GPUs per model; the paper notes that RL hyper-parameters have a disproportionately large influence on training.
对于 Qwen2.5-VL-3B,DIFT 训练 1 个 epoch,批大小 1,AdamW 学习率 1e-5,K = 4,λce = 0.1,λsim = 1.0,视频按 1 FPS 采样,在 8 张 H200 上用 DeepSpeed ZeRO-2 训练。4DRL 使用 G = 8、λacc = 1.0、λfmt = 0.2、学习率 1e-6、最长 8,192 个 token 的回答、β = 0.01、批大小 8、梯度累积 2 步。不同基座的设置略有差异,最大的模型(如 InternVL3.5-38B)每个最多用到 64 张 H200;论文指出强化学习的超参数对训练影响格外大。
The released scripts match these values: dift/train.sh sets LR=1e-5, LATENT_SIZE=4, CE_LOSS_WEIGHT=0.1, SIM_LOSS_WEIGHT=1.0 and FPS=1, and 4drl/run_scripts/train_4dthinker.sh passes --reward_funcs accuracy format --reward_weights 1.0 0.2, LR=1e-6, NUM_GENERATIONS=8, BETA=0.01 and MAX_COMPLETION_LENGTH=8192. The RL trainer removes the latent token ids from the loss mask. Two details differ from the paper’s text: the RL script passes --freeze_vision_modules false, while the paper says the vision encoder stays frozen in every stage, and the format reward’s regular expression checks only <think>…</think><answer>…</answer>.
开源脚本与这些数值一致:dift/train.sh 设置 LR=1e-5、LATENT_SIZE=4、CE_LOSS_WEIGHT=0.1、SIM_LOSS_WEIGHT=1.0 和 FPS=1;4drl/run_scripts/train_4dthinker.sh 传入 --reward_funcs accuracy format --reward_weights 1.0 0.2、LR=1e-6、NUM_GENERATIONS=8、BETA=0.01 和 MAX_COMPLETION_LENGTH=8192。强化学习训练器会把潜在 token 的 id 从损失掩码中去掉。有两处与论文正文不同:强化学习脚本传入 --freeze_vision_modules false,而论文说视觉编码器在所有阶段都保持冻结;格式奖励的正则表达式只检查 <think>…</think><answer>…</answer>。
Environment, training and evaluation commands环境、训练与评测命令
The README uses two conda environments, each with its own customised transformers fork (dift/transformers and 4drl/transformers_rl), plus a bundled trl for RL. Evaluation on DSR-Bench uses evaluation/dsr_eval.py.
README 使用两套 conda 环境,各自安装定制的 transformers 分支(dift/transformers 与 4drl/transformers_rl),强化学习还要用仓库自带的 trl。DSR-Bench 评测使用 evaluation/dsr_eval.py。
# DIFT environment
conda create -n 4dthinker python=3.10 -y
conda activate 4dthinker
pip install -r dift/requirements_dift.txt
cd dift && pip install -e ./transformers/ && cd ..

# 4DRL environment
conda create -n 4dthinker-rl python=3.10 -y
conda activate 4dthinker-rl
pip install -r 4drl/requirements_4drl.txt
cd 4drl
pip install -e ./transformers_rl/
cp -rf ./trl $(python -c "import site; print(site.getsitepackages()[0])")/trl
pip install -e ./src/open-r1-multimodal/
cd ..

# Training
conda activate 4dthinker && bash dift/train.sh
conda activate 4dthinker-rl && bash 4drl/run_scripts/train_4dthinker.sh

# DSR-Bench evaluation
CUDA_VISIBLE_DEVICES=0 python evaluation/dsr_eval.py \
    --model_path model/dift/checkpoints \
    --benchmark_path ./raw_data/DSR_Suite-Data/benchmark.parquet \
    --video_root ./raw_data/DSR-data/bmk_video \
    --latent_size 4
The README names the RL environment 4dthinker-rl when creating it and 4dthinker-4drl when activating it; the listing above uses one name for both.
README 创建强化学习环境时命名为 4dthinker-rl,激活时却写成 4dthinker-4drl;上面的命令统一使用前者。
3DThinker results3DThinker 的结果
Multiple-choice questions are scored by exact-match accuracy; numerical answers use the mean relative accuracy of VSI-Bench. MindCube-Tiny has 1,050 questions over three camera motions: Rotation (the camera turns in place), Around (it circles the objects) and Among (it moves among them). Ego3D-Bench has over 8,600 questions on ego-centric multi-view outdoor scenes: absolute distance, relative distance, localisation, motion and travel time, asked from the ego vehicle or from an object.
选择题按完全匹配计算准确率;数值题采用 VSI-Bench 的平均相对准确率(MRA)。MindCube-Tiny 有 1,050 道题,涵盖三种相机运动:Rotation(相机原地旋转)、Around(绕物体环行)和 Among(在物体之间穿行)。Ego3D-Bench 有 8,600 多道题,场景是以自我为中心的多视角户外环境,题型包括绝对距离、相对距离、定位、运动和行程时间,分别从自车和物体的角度提问。
Generalist VLMs on MindCube-Tiny and Ego3D-Bench通用 VLM 在 MindCube-Tiny 与 Ego3D-Bench 上的表现
Table 4 trains eight Qwen2.5-VL and InternVL3 models on MindCube-only and every one improves on both benchmarks. On Qwen2.5-VL-3B, Stage 1 lifts MindCube-Tiny from 33.2 to 62.7 (+88.9%) and Stage 2 to 75.2 (+19.9%); on Ego3D-Bench it goes from 39.1 to 46.7 and then 50.8. Across the eight models, S1+S2 raises the MindCube-Tiny overall score by 58.1% to 126.5% and the Ego3D-Bench average by 18.8% to 40.1%. Ego3D-Bench is out of domain: no Ego3D data is used in training. The best model, InternVL3-78B with both stages, scores 78.9 on MindCube-Tiny and 73.3 on Ego3D-Bench, above every closed model, o3 included (56.6 and 73.0).
表 4 在 MindCube-only 数据上训练了 8 个 Qwen2.5-VL 和 InternVL3 模型,每个模型在两个基准上都有提升。以 Qwen2.5-VL-3B 为例,阶段 1 把 MindCube-Tiny 从 33.2 提高到 62.7(+88.9%),阶段 2 再提高到 75.2(+19.9%);Ego3D-Bench 从 39.1 提高到 46.7,再到 50.8。在这 8 个模型上,S1+S2 使 MindCube-Tiny 总分提高 58.1% 到 126.5%,Ego3D-Bench 平均分提高 18.8% 到 40.1%。Ego3D-Bench 属于域外测试:训练中没有用到任何 Ego3D 数据。最好的模型是经过两个阶段训练的 InternVL3-78B,在 MindCube-Tiny 和 Ego3D-Bench 上分别得到 78.9 和 73.3,超过所有闭源模型,包括 o3(56.6 和 73.0)。
Travel time is the weak spot. Stage 2 leaves it at or slightly below Stage 1 on six of the eight models, and on Qwen2.5-VL-3B it never moves past the base model (30.9, then 30.8 and 30.8). The paper’s explanation is that mapping normalised 3D representations onto real-world distances and times needs richer context.
行程时间是短板。在 8 个模型中有 6 个,阶段 2 在这一项上与阶段 1 持平或略低;在 Qwen2.5-VL-3B 上,它始终没有超过基座模型(30.9,之后为 30.8 和 30.8)。论文的解释是,要把归一化的 3D 表示对应到真实世界的距离和时间,还需要更丰富的上下文信息。
Table 4Generalist VLMs and 3DThinker on MindCube-Tiny and Ego3D-Bench, accuracy %. 3DThinker rows are trained from the base model above them on MindCube-only, after Stage 1 (S1) and after both stages (S1+S2, shaded). Blue marks the best result per base model (per block for the closed models). The paper bolds o3’s 83.1 on Obj. Rel.; doubao-seed-1.6’s 86.0 is higher and is marked here. Overall best: InternVL3-78B with S1+S2, 78.9 and 73.3.表 4MindCube-Tiny 与 Ego3D-Bench 上通用 VLM 与 3DThinker 的准确率(%)。3DThinker 各行都在其上方的基座模型上用 MindCube-only 数据训练,分别为阶段 1 后(S1)和两个阶段后(S1+S2,加底色)。蓝色为每个基座模型内的最佳(闭源模型按整组计)。论文在“物体相对”一列把 o3 的 83.1 标为最佳,但 doubao-seed-1.6 的 86.0 更高,此处标后者。全表最佳为经 S1+S2 训练的 InternVL3-78B:78.9 和 73.3。
| Model模型 | MindCube-Tiny | Ego3D-Bench | |||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Rotation旋转 | Among穿行 | Around环绕 | Overall总体 | Ego Dist.自我 距离 | Obj. Dist.物体 距离 | Loc.定位 | Ego Mot.自我 运动 | Obj. Mot.物体 运动 | Travel Time行程 时间 | Ego Rel.自我 相对 | Obj. Rel.物体 相对 | Avg.平均 | |
| Closed-source models闭源模型 | |||||||||||||
| gpt-4o-2024-11-20 | 37.0 | 44.8 | 56.4 | 46.1 | 33.2 | 26.5 | 28.1 | 78.1 | 56.7 | 36.0 | 60.5 | 66.0 | 48.1 |
| gpt-4.1 | 45.5 | 44.2 | 47.2 | 45.1 | 51.7 | 36.2 | 41.8 | 82.7 | 62.6 | 44.3 | 65.7 | 70.2 | 56.9 |
| glm-4.5v | 28.0 | 43.0 | 33.2 | 37.8 | 49.9 | 39.6 | 48.4 | 88.8 | 73.4 | 40.4 | 57.1 | 81.9 | 59.9 |
| gemini-2.5-pro | 84.0 | 39.7 | 56.8 | 52.2 | 58.5 | 50.2 | 61.4 | 92.9 | 75.5 | 43.5 | 72.8 | 78.6 | 66.7 |
| claude-sonnet-4 | 49.5 | 42.2 | 12.8 | 36.6 | 48.9 | 36.5 | 51.6 | 81.9 | 55.1 | 33.6 | 53.9 | 69.5 | 53.9 |
| doubao-seed-1.6 | 87.0 | 35.8 | 38.0 | 46.1 | 55.2 | 50.8 | 60.5 | 89.0 | 67.3 | 49.8 | 71.4 | 86.0 | 66.3 |
| o3-2025-04-16 | 86.5 | 42.7 | 66.0 | 56.6 | 71.3 | 59.3 | 65.6 | 93.4 | 80.1 | 53.5 | 77.7 | 83.1 | 73.0 |
| Qwen2.5-VL familyQwen2.5-VL 系列 | |||||||||||||
| Qwen2.5-VL-3B | 37.4 | 33.3 | 30.3 | 33.2 | 21.5 | 29.4 | 28.8 | 50.3 | 41.9 | 30.9 | 54.1 | 56.1 | 39.1 |
| 3DThinker-S1 | 44.0 | 64.8 | 72.4 | 62.7 | 36.1 | 39.4 | 32.5 | 54.8 | 46.2 | 30.8 | 64.0 | 69.7 | 46.7 |
| 3DThinker-S1+S2 | 55.5 | 81.8 | 75.2 | 75.2 | 41.6 | 46.0 | 33.1 | 54.7 | 53.3 | 30.8 | 70.1 | 76.9 | 50.8 |
| Qwen2.5-VL-7B | 36.5 | 32.5 | 38.4 | 34.7 | 32.7 | 31.5 | 30.5 | 45.9 | 44.0 | 34.5 | 43.2 | 66.5 | 41.1 |
| 3DThinker-S1 | 43.5 | 66.3 | 76.4 | 64.4 | 47.9 | 44.5 | 36.5 | 51.9 | 51.3 | 39.1 | 59.1 | 73.9 | 50.5 |
| 3DThinker-S1+S2 | 55.0 | 83.0 | 76.0 | 76.0 | 54.0 | 52.3 | 36.5 | 52.7 | 56.6 | 38.2 | 66.0 | 83.1 | 54.9 |
| Qwen2.5-VL-32B | 39.5 | 34.5 | 43.6 | 37.6 | 45.4 | 40.7 | 49.6 | 75.6 | 74.1 | 40.1 | 54.0 | 79.0 | 57.3 |
| 3DThinker-S1 | 45.0 | 66.8 | 77.2 | 65.1 | 52.0 | 51.9 | 54.8 | 80.1 | 79.4 | 44.3 | 62.0 | 83.1 | 63.5 |
| 3DThinker-S1+S2 | 56.5 | 83.2 | 77.2 | 76.7 | 62.2 | 61.9 | 54.5 | 80.2 | 86.6 | 43.7 | 69.9 | 86.0 | 68.1 |
| Qwen2.5-VL-72B | 40.0 | 42.5 | 44.4 | 42.5 | 42.4 | 38.6 | 54.8 | 86.8 | 68.9 | 38.5 | 53.3 | 80.5 | 58.0 |
| 3DThinker-S1 | 42.5 | 68.0 | 73.6 | 64.5 | 49.9 | 45.9 | 57.8 | 85.6 | 75.6 | 43.9 | 58.0 | 80.8 | 62.2 |
| 3DThinker-S1+S2 | 57.0 | 83.7 | 77.6 | 77.1 | 61.1 | 59.9 | 59.7 | 93.1 | 84.9 | 43.7 | 69.8 | 87.8 | 70.0 |
| InternVL3 familyInternVL3 系列 | |||||||||||||
| InternVL3-8B | 37.0 | 40.3 | 63.2 | 45.1 | 25.8 | 28.7 | 29.8 | 54.1 | 54.8 | 36.1 | 49.9 | 65.2 | 43.1 |
| 3DThinker-S1 | 43.0 | 66.8 | 79.2 | 65.2 | 43.8 | 44.4 | 32.9 | 60.6 | 61.2 | 46.9 | 64.1 | 72.1 | 53.3 |
| 3DThinker-S1+S2 | 55.0 | 82.5 | 79.2 | 76.5 | 54.6 | 56.1 | 36.0 | 67.2 | 69.4 | 46.7 | 71.0 | 81.9 | 60.4 |
| InternVL3-14B | 36.0 | 48.0 | 55.6 | 47.5 | 46.0 | 35.6 | 35.9 | 63.2 | 65.9 | 41.6 | 55.5 | 70.1 | 51.7 |
| 3DThinker-S1 | 42.0 | 68.3 | 77.2 | 65.4 | 56.2 | 49.1 | 37.3 | 70.0 | 71.8 | 51.1 | 68.0 | 77.7 | 60.2 |
| 3DThinker-S1+S2 | 54.5 | 84.3 | 77.6 | 77.0 | 63.5 | 59.9 | 41.3 | 78.3 | 80.2 | 50.0 | 75.1 | 84.0 | 66.5 |
| InternVL3-38B | 32.5 | 48.5 | 56.0 | 47.2 | 35.4 | 31.0 | 39.4 | 66.6 | 64.9 | 38.0 | 61.0 | 77.3 | 51.7 |
| 3DThinker-S1 | 39.0 | 68.0 | 76.8 | 64.6 | 44.8 | 47.0 | 43.6 | 73.1 | 68.6 | 48.5 | 71.2 | 79.1 | 59.5 |
| 3DThinker-S1+S2 | 53.5 | 85.2 | 78.0 | 77.4 | 54.7 | 58.1 | 49.2 | 86.9 | 80.4 | 49.1 | 79.6 | 85.9 | 68.0 |
| InternVL3-78B | 38.5 | 50.5 | 57.4 | 49.9 | 54.6 | 48.4 | 50.3 | 77.7 | 70.0 | 44.8 | 57.0 | 76.6 | 59.9 |
| 3DThinker-S1 | 43.5 | 69.0 | 77.2 | 66.1 | 59.8 | 53.1 | 52.2 | 80.1 | 72.5 | 53.9 | 65.1 | 78.0 | 64.3 |
| 3DThinker-S1+S2 | 57.0 | 86.2 | 78.8 | 78.9 | 69.9 | 61.0 | 61.0 | 91.9 | 88.6 | 54.8 | 75.3 | 83.9 | 73.3 |
Against spatial models on six more benchmarks在另外六个基准上对比空间推理模型
Table 5 trains on the large-scale curated set and compares with recent spatial models built on the same base. On Qwen2.5-VL-3B, 3DThinker averages 55.3 after Stage 1 and 60.4 after Stage 2, 11.5% and 21.8% above SpatialLadder-3B (49.6). On Qwen2.5-VL-7B the margin over VILASR-7B (48.4) is 22.7% and 33.7% (59.4 and 64.7). SpatialLadder-3B leads on its own SPBench, while 3DThinker improves on every benchmark. It also stays strong on single-image CV-Bench (78.4 and 81.1), where Video-R1 falls below its base model.
表 5 使用大规模精选数据训练,并与基于同一基座的近期空间推理模型比较。在 Qwen2.5-VL-3B 上,3DThinker 阶段 1 后平均 55.3,阶段 2 后 60.4,分别比 SpatialLadder-3B(49.6)高 11.5% 和 21.8%。在 Qwen2.5-VL-7B 上,相对 VILASR-7B(48.4)的优势为 22.7% 和 33.7%(59.4 和 64.7)。SpatialLadder-3B 在它自己的 SPBench 上领先,而 3DThinker 在每个基准上都有提升。在单图的 CV-Bench 上它同样表现很好(78.4 和 81.1),Video-R1 在这里反而低于其基座模型。
Table 5Spatial models on six more benchmarks, accuracy %. SI: single image, MV: multiple views. 3DThinker rows (*) are trained on the large-scale curated set; S1+S2 shaded. Blue marks the best per base model, as in the paper.表 5另外六个空间推理基准上各空间模型的准确率(%)。SI:单图,MV:多视角。3DThinker 各行(*)使用大规模精选数据训练;S1+S2 加底色。蓝色为每个基座模型内的最佳,与论文一致。
| Model模型 | VSI-BenchMV | SPBenchSI · MV | CV-BenchSI | SPAR-BenchSI · MV | ViewSpatial-BenchSI · MV | MMSI-BenchMV | Avg.平均 |
|---|---|---|---|---|---|---|---|
| Spatial models on Qwen2.5-VL-3B基于 Qwen2.5-VL-3B 的空间模型 | |||||||
| Qwen2.5-VL-3B | 29.4 | 38.5 | 70.6 | 24.6 | 35.6 | 26.5 | 37.5 |
| Spatial-MLLM-4B | 47.3 | 48.4 | 73.8 | 35.1 | 43.6 | 31.5 | 46.6 |
| SpatialLadder-3B | 45.7 | 70.6 | 73.7 | 34.4 | 44.2 | 29.2 | 49.6 |
| 3DThinker-S1* | 53.2 | 54.8 | 74.5 | 52.3 | 59.5 | 37.7 | 55.3 |
| 3DThinker-S1+S2* | 59.1 | 60.2 | 78.4 | 58.2 | 64.7 | 41.9 | 60.4 |
| Spatial models on Qwen2.5-VL-7B基于 Qwen2.5-VL-7B 的空间模型 | |||||||
| Qwen2.5-VL-7B | 35.8 | 42.9 | 73.0 | 30.2 | 37.9 | 26.9 | 41.1 |
| SpaceR-7B | 44.5 | 54.0 | 75.3 | 37.1 | 45.5 | 28.8 | 47.5 |
| VILASR-7B | 45.4 | 53.9 | 77.1 | 37.8 | 46.1 | 30.2 | 48.4 |
| Video-R1 | 33.4 | 42.8 | 69.6 | 31.5 | 36.1 | 29.4 | 40.5 |
| 3DThinker-S1* | 57.3 | 61.5 | 77.9 | 56.3 | 61.7 | 41.5 | 59.4 |
| 3DThinker-S1+S2* | 63.7 | 68.3 | 81.1 | 63.3 | 68.6 | 43.3 | 64.7 |
Against Ego3D-VLM across model sizes在不同模型规模上对比 Ego3D-VLM
Ego3D-VLM builds a cognitive map with Grounding-DINO-Base for referring expressions and Depth-Anything-V2-Metric-Large for depth. 3DThinker uses no external module at inference, yet matches or beats it on all eight models (Table 6), by 14.4% on Qwen2.5-VL-3B (50.8 vs 44.4); the two tie on InternVL3-38B.
Ego3D-VLM 借助 Grounding-DINO-Base(指代表达理解)和 Depth-Anything-V2-Metric-Large(深度估计)构建认知地图。3DThinker 推理时不依赖任何外部模块,却在全部 8 个模型上持平或超过它(表 6),在 Qwen2.5-VL-3B 上高出 14.4%(50.8 对 44.4);两者在 InternVL3-38B 上打平。
Table 6Ego3D-Bench average accuracy % against Ego3D-VLM, which builds cognitive maps with external detection and depth models, across two model families and eight sizes. The 3DThinker numbers are the S1+S2 averages of Table 4. Blue marks the better of the two; both are marked where they tie.表 6Ego3D-Bench 平均准确率(%):与借助外部检测、深度模型构建认知地图的 Ego3D-VLM 比较,覆盖两个模型系列、八种规模。3DThinker 的数字即表 4 中 S1+S2 的平均分。蓝色为两者中更好的一方,持平时都标出。
| Method方法 | Qwen2.5-VL | InternVL3 | ||||||
|---|---|---|---|---|---|---|---|---|
| 3B | 7B | 32B | 72B | 8B | 14B | 38B | 78B | |
| Ego3D-VLM | 44.4 | 54.3 | 65.5 | 69.5 | 60.1 | 66.1 | 68.0 | 71.8 |
| 3DThinker | 50.8 | 54.9 | 68.1 | 70.0 | 60.4 | 66.5 | 68.0 | 73.3 |
Qwen3-VL and LLaVA-OneVision-1.5Qwen3-VL 与 LLaVA-OneVision-1.5
The supplementary material repeats the recipe on newer bases. Qwen3-VL already reserves <think> as a special token, so its reasoning tag becomes <thinking>, and the mixture-of-experts Qwen3-VL-30B-A3B is trained in Stage 2 with sequence-level GSPO instead of token-level GRPO for stability. MindCube-Tiny rises from 26.0 to 75.8 on Qwen3-VL-4B, from near chance to accurate, and Ego3D-Bench by up to 29.9% (43.2 to 56.1 on Qwen3-VL-2B) (Table 7). On LLaVA-OneVision-1.5, the 8B model goes from 37.9 to 63.7 on MindCube-Tiny and from 45.3 to 48.7 on Ego3D-Bench (Table 8).
补充材料在更新的基座上复用了同一套方法。Qwen3-VL 已把 <think> 预留为特殊 token,因此推理标签改为 <thinking>;混合专家模型 Qwen3-VL-30B-A3B 在阶段 2 中改用序列级的 GSPO 代替 token 级的 GRPO,以保持训练稳定。MindCube-Tiny 在 Qwen3-VL-4B 上从 26.0 提升到 75.8,从接近随机猜测变为高准确率;Ego3D-Bench 最多提升 29.9%(Qwen3-VL-2B 从 43.2 到 56.1)(表 7)。在 LLaVA-OneVision-1.5 上,8B 模型的 MindCube-Tiny 从 37.9 提高到 63.7,Ego3D-Bench 从 45.3 提高到 48.7(表 8)。
Table 7Qwen3-VL as the base, accuracy %, from the 3DThinker paper’s supplementary material (columns as in Table 4). Qwen3-VL-30B-A3B is a mixture-of-experts model and uses GSPO in Stage 2. S1+S2 shaded; blue marks the best per base model.表 7以 Qwen3-VL 为基座的准确率(%),取自 3DThinker 论文补充材料(列同表 1)。Qwen3-VL-30B-A3B 为混合专家模型,阶段 2 使用 GSPO。S1+S2 加底色;蓝色为每个基座模型内的最佳。
| Model模型 | MindCube-Tiny | Ego3D-Bench | |||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Rotation旋转 | Among穿行 | Around环绕 | Overall总体 | Ego Dist.自我 距离 | Obj. Dist.物体 距离 | Loc.定位 | Ego Mot.自我 运动 | Obj. Mot.物体 运动 | Travel Time行程 时间 | Ego Rel.自我 相对 | Obj. Rel.物体 相对 | Avg.平均 | |
| Qwen3-VL-2B | 29.0 | 32.2 | 46.8 | 35.0 | 24.7 | 23.9 | 30.4 | 58.7 | 56.4 | 32.8 | 57.4 | 61.1 | 43.2 |
| 3DThinker-S1 | 40.5 | 67.5 | 77.2 | 64.7 | 45.9 | 41.6 | 36.0 | 60.6 | 59.2 | 37.2 | 62.0 | 72.1 | 51.8 |
| 3DThinker-S1+S2 | 53.0 | 83.2 | 78.4 | 76.2 | 53.1 | 51.3 | 36.4 | 61.4 | 62.8 | 38.2 | 65.3 | 80.5 | 56.1 |
| Qwen3-VL-4B | 34.0 | 18.7 | 37.2 | 26.0 | 41.3 | 40.9 | 27.9 | 56.9 | 56.6 | 37.8 | 60.1 | 68.2 | 48.7 |
| 3DThinker-S1 | 43.0 | 65.3 | 76.0 | 63.6 | 54.0 | 49.9 | 35.1 | 59.3 | 60.8 | 40.8 | 64.9 | 76.1 | 55.1 |
| 3DThinker-S1+S2 | 55.0 | 81.7 | 78.4 | 75.8 | 62.3 | 56.5 | 35.5 | 61.4 | 64.1 | 40.4 | 68.3 | 84.0 | 59.1 |
| Qwen3-VL-8B | 31.5 | 31.0 | 41.2 | 33.5 | 38.9 | 32.6 | 31.6 | 45.3 | 56.8 | 40.8 | 62.4 | 69.3 | 47.2 |
| 3DThinker-S1 | 42.0 | 67.8 | 76.8 | 65.0 | 52.1 | 45.9 | 37.1 | 51.5 | 61.8 | 43.2 | 67.8 | 78.2 | 54.7 |
| 3DThinker-S1+S2 | 56.5 | 82.5 | 78.8 | 76.7 | 63.0 | 56.8 | 38.1 | 55.5 | 66.2 | 43.2 | 71.1 | 86.1 | 60.0 |
| Qwen3-VL-32B | 29.5 | 33.5 | 38.0 | 33.8 | 51.5 | 40.7 | 40.9 | 76.4 | 58.2 | 40.4 | 61.5 | 81.4 | 56.4 |
| 3DThinker-S1 | 41.0 | 69.5 | 77.6 | 66.1 | 60.4 | 51.0 | 48.3 | 78.6 | 67.9 | 43.2 | 68.1 | 87.3 | 63.1 |
| 3DThinker-S1+S2 | 55.0 | 84.2 | 79.6 | 77.5 | 69.3 | 62.2 | 48.7 | 85.1 | 73.5 | 43.0 | 73.1 | 90.3 | 68.2 |
| Qwen3-VL-30B-A3B | 37.0 | 43.9 | 45.6 | 42.9 | 49.1 | 45.8 | 28.4 | 64.5 | 60.0 | 34.7 | 63.3 | 73.3 | 52.4 |
| 3DThinker-S1 | 46.5 | 72.8 | 82.0 | 70.0 | 60.1 | 54.4 | 38.3 | 72.2 | 70.3 | 38.0 | 71.0 | 80.1 | 60.6 |
| 3DThinker-S1+S2 | 60.0 | 86.7 | 83.2 | 80.8 | 69.4 | 65.1 | 39.1 | 79.3 | 75.1 | 37.6 | 76.3 | 88.0 | 66.2 |
Table 8LLaVA-OneVision-1.5 as the base, accuracy %, from the 3DThinker paper’s supplementary material (columns as in Table 4). S1+S2 shaded; blue marks the best per base model.表 8以 LLaVA-OneVision-1.5 为基座的准确率(%),取自 3DThinker 论文补充材料(列同表 1)。S1+S2 加底色;蓝色为每个基座模型内的最佳。
| Model模型 | MindCube-Tiny | Ego3D-Bench | |||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Rotation旋转 | Among穿行 | Around环绕 | Overall总体 | Ego Dist.自我 距离 | Obj. Dist.物体 距离 | Loc.定位 | Ego Mot.自我 运动 | Obj. Mot.物体 运动 | Travel Time行程 时间 | Ego Rel.自我 相对 | Obj. Rel.物体 相对 | Avg.平均 | |
| LLaVA-OneVision-1.5-4B | 33.5 | 38.0 | 49.2 | 39.8 | 39.7 | 37.1 | 29.2 | 51.4 | 51.8 | 34.1 | 52.4 | 73.5 | 46.2 |
| 3DThinker-S1 | 41.5 | 59.8 | 66.0 | 57.8 | 40.0 | 39.1 | 33.1 | 51.1 | 52.6 | 30.9 | 58.6 | 73.8 | 47.4 |
| 3DThinker-S1+S2 | 48.0 | 67.5 | 65.2 | 63.2 | 40.2 | 39.9 | 34.2 | 51.9 | 52.3 | 30.8 | 61.8 | 73.8 | 48.1 |
| LLaVA-OneVision-1.5-8B | 34.5 | 34.7 | 48.4 | 37.9 | 30.3 | 36.6 | 34.3 | 44.9 | 51.9 | 36.9 | 53.4 | 74.4 | 45.3 |
| 3DThinker-S1 | 43.0 | 57.8 | 64.8 | 56.7 | 35.1 | 39.0 | 36.1 | 44.9 | 53.2 | 31.9 | 61.0 | 73.8 | 46.9 |
| 3DThinker-S1+S2 | 49.0 | 68.2 | 64.8 | 63.7 | 36.5 | 41.5 | 37.0 | 46.2 | 53.3 | 32.8 | 64.9 | 77.2 | 48.7 |
3DSRBench and general benchmarks3DSRBench 与通用基准
On 3DSRBench, 3DThinker scores 65.6, 8.79% above the best earlier method, SpatialReasoner (60.3) (Table 9). On general image benchmarks the Qwen2.5-VL-7B-based model keeps its base model’s abilities: POPE rises from 85.9 to 88.4 and SEED-Image from 77.0 to 78.9, while MME, mostly 2D tasks such as OCR and numerical reasoning, stays comparable (Table 10).
在 3DSRBench 上,3DThinker 得到 65.6,比此前最好的 SpatialReasoner(60.3)高 8.79%(表 9)。在通用图像基准上,基于 Qwen2.5-VL-7B 的模型保留了基座模型的能力:POPE 从 85.9 提高到 88.4,SEED-Image 从 77.0 提高到 78.9;以 OCR、数值推理等 2D 任务为主的 MME 与基座相当(表 10)。
Table 93DSRBench accuracy %, from the 3DThinker paper’s supplementary material. 3DThinker (*) is trained on the large-scale curated set.表 93DSRBench 准确率(%),取自 3DThinker 论文补充材料。3DThinker(*)使用大规模精选数据训练。
| Model模型 | 3DSRBench |
|---|---|
| SpatialReasoner | 60.3 |
| SpatialReasoner-R1 | 55.7 |
| SpatialThinker | 56.4 |
| 3DThinker* | 65.6 |
Table 10General image benchmarks, from the 3DThinker paper’s supplementary material: MME perception (MMEP) and cognition (MMEC) scores, POPE and SEED-Image accuracy %. 3DThinker (*) is built on Qwen2.5-VL-7B with the large-scale curated set. Blue marks the better of the two.表 10通用图像基准,取自 3DThinker 论文补充材料:MME 感知(MMEP)与认知(MMEC)得分,POPE 与 SEED-Image 准确率(%)。3DThinker(*)基于 Qwen2.5-VL-7B,使用大规模精选数据训练。蓝色为两者中更好的一方。
| Model模型 | MMEP | MMEC | POPE | SEED-I |
|---|---|---|---|---|
| Qwen2.5-VL-7B | 1670 | 623 | 85.9 | 77.0 |
| 3DThinker* | 1677 | 610 | 88.4 | 78.9 |
4DThinker results4DThinker 的结果
Both benchmarks are multiple choice and scored by exact-match accuracy. DSR-Bench measures how geometric quantities evolve in dynamic scenes, in 13 subtasks: distance, direction, orientation, speed, speed comparison and direction prediction, each with an absolute viewpoint fixed at one moment (A.) or a relative one that moves with the observer (R.), plus free-form non-template questions (N-Temp). Dyn-Bench tests semantic understanding of dynamics on 1K videos and 7K questions along three axes: inter-object, object–scene and camera–object; 4DThinker does not use its mask data.
两个基准都是选择题,按完全匹配计算准确率。DSR-Bench 衡量动态场景中几何量如何变化,共 13 个子任务:距离、方向、朝向、速度、速度比较和方向预测,每类又分为固定在某一时刻的绝对视角(A.)和随观察者移动的相对视角(R.),另有非模板的自由提问(N-Temp)。Dyn-Bench 在 1K 段视频、7K 个问题上考察对动态内容的语义理解,分为物体之间、物体与场景、相机与物体三个维度;4DThinker 没有使用其中的掩码数据。
Fine-grained 4D reasoning on DSR-BenchDSR-Bench 上的细粒度 4D 推理
4DThinker improves the average of every base model (Table 11). On Qwen2.5-VL-3B, DIFT adds 6.5 points (24.6 to 31.1) and 4DRL brings it to 34.2; one subtask, R.SpdC, drops there (29.0 to 26.8). The gains grow with scale: Qwen3-VL-32B goes from 28.0 to 62.0 (+34.0), above Gemini-2.5-Pro (31.7) and above DSR Suite-Model (58.9), the previous best, which injects 3D priors through a geometry selection module; InternVL3.5-38B gains 32.7 (26.7 to 59.4). The largest jumps come on absolute subtasks where base models sit near chance, around 20%: A.Dis on Qwen3-VL-32B rises from 14.5 to 84.3. The paper reads this as the 4D latents supplying geometric grounding that language-only reasoning lacks.
4DThinker 提升了每一个基座模型的平均分(表 11)。在 Qwen2.5-VL-3B 上,DIFT 提高 6.5 分(24.6 到 31.1),加上 4DRL 后达到 34.2;其中 R.SpdC 一项有所下降(29.0 到 26.8)。模型越大提升越明显:Qwen3-VL-32B 从 28.0 提高到 62.0(+34.0),超过 Gemini-2.5-Pro(31.7),也超过此前最好的 DSR Suite-Model(58.9),后者借助几何选择模块注入 3D 先验;InternVL3.5-38B 提高 32.7 分(26.7 到 59.4)。提升最大的是基座模型接近随机水平(约 20%)的绝对视角子任务:Qwen3-VL-32B 的 A.Dis 从 14.5 提高到 84.3。论文认为这说明 4D 潜在 token 提供了纯语言推理所缺的几何依据。
Table 11DSR-Bench accuracy %, from the 4DThinker paper. A.: absolute viewpoint, R.: relative viewpoint; Dis distance, Dir direction, Ori orientation, Spd speed, SpdC speed comparison, DirP direction prediction, N-Temp non-template questions. 4DThinker rows are trained from the base model above them; DIFT + 4DRL shaded. Blue marks the best in each column. Avg. is as reported; it is not the plain mean of the 13 columns (the paper calls it the mean across subtasks).表 11DSR-Bench 准确率(%),取自 4DThinker 论文。A.:绝对视角,R.:相对视角;Dis 距离,Dir 方向,Ori 朝向,Spd 速度,SpdC 速度比较,DirP 方向预测,N-Temp 非模板问题。4DThinker 各行都在其上方的基座模型上训练;DIFT + 4DRL 加底色。蓝色为每列最佳。平均分照录论文,并不等于 13 列的简单平均(论文称其为各子任务的平均)。
| Model模型 | A.Dis | A.Dir | A.Ori | A.Spd | A.SpdC | A.DirP | R.Dis | R.Dir | R.Ori | R.Spd | R.SpdC | R.DirP | N-Temp | Avg.平均 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Proprietary models闭源模型 | ||||||||||||||
| GPT-5 | 21.1 | 41.5 | 48.7 | 34.5 | 33.3 | 34.7 | 17.2 | 44.3 | 41.9 | 21.2 | 25.0 | 30.9 | 26.7 | 30.8 |
| Gemini-2.5-Pro | 20.0 | 44.6 | 53.6 | 27.3 | 38.7 | 30.5 | 23.2 | 32.9 | 43.2 | 17.1 | 28.5 | 27.9 | 34.3 | 31.7 |
| Spatial understanding models空间理解模型 | ||||||||||||||
| VLM-3R | 28.2 | 27.6 | 31.7 | 42.8 | 38.7 | 33.0 | 34.4 | 23.8 | 30.8 | 22.2 | 26.4 | 29.1 | 35.0 | 31.4 |
| VG-LLM | 55.2 | 32.3 | 58.5 | 57.1 | 51.6 | 32.2 | 56.0 | 36.3 | 32.0 | 30.3 | 32.1 | 29.1 | 27.9 | 38.4 |
| DSR Suite-Model | 87.0 | 73.8 | 84.1 | 73.8 | 72.0 | 35.5 | 75.8 | 76.1 | 77.7 | 60.6 | 37.1 | 35.1 | 46.4 | 58.9 |
| 4DThinker on different base models不同基座上的 4DThinker | ||||||||||||||
| Qwen2.5-VL-3B | 20.5 | 20.3 | 20.3 | 37.0 | 17.6 | 22.6 | 25.5 | 20.7 | 25.6 | 23.7 | 29.0 | 24.2 | 27.0 | 24.6 |
| + DIFT | 48.2 | 28.1 | 25.3 | 46.9 | 28.6 | 28.7 | 35.8 | 29.9 | 37.2 | 24.7 | 25.3 | 31.1 | 26.6 | 31.1 |
| + DIFT + 4DRL | 50.6 | 34.4 | 29.1 | 56.8 | 34.1 | 34.8 | 49.1 | 33.3 | 30.8 | 27.8 | 26.8 | 28.6 | 27.5 | 34.2 |
| Qwen2.5-VL-7B | 18.8 | 15.3 | 14.6 | 42.8 | 29.0 | 19.4 | 31.8 | 19.3 | 11.1 | 22.2 | 19.2 | 20.2 | 30.1 | 23.5 |
| + DIFT | 45.8 | 35.9 | 34.2 | 50.6 | 37.4 | 29.6 | 40.6 | 37.9 | 35.9 | 30.9 | 19.6 | 27.3 | 38.6 | 34.8 |
| + DIFT + 4DRL | 71.1 | 62.5 | 60.8 | 70.4 | 49.5 | 39.1 | 60.4 | 47.1 | 43.6 | 38.1 | 32.6 | 32.3 | 42.5 | 47.1 |
| Qwen3-VL-8B | 23.5 | 24.6 | 42.6 | 29.7 | 27.9 | 33.8 | 18.1 | 28.4 | 34.5 | 24.2 | 22.1 | 27.9 | 33.5 | 28.7 |
| + DIFT | 51.8 | 45.3 | 55.7 | 44.4 | 37.4 | 42.6 | 50.0 | 47.1 | 44.9 | 42.3 | 35.5 | 32.9 | 40.8 | 42.6 |
| + DIFT + 4DRL | 78.3 | 65.6 | 82.3 | 59.3 | 58.2 | 46.1 | 59.4 | 63.2 | 61.5 | 58.8 | 39.1 | 36.6 | 47.2 | 54.6 |
| Qwen3-VL-32B | 14.5 | 37.5 | 24.1 | 43.2 | 27.5 | 38.3 | 13.2 | 32.2 | 38.5 | 17.5 | 20.3 | 28.0 | 31.8 | 28.0 |
| + DIFT | 53.0 | 65.6 | 40.5 | 45.7 | 56.0 | 41.7 | 50.9 | 48.3 | 46.2 | 43.3 | 37.7 | 34.8 | 44.2 | 45.2 |
| + DIFT + 4DRL | 84.3 | 79.7 | 82.3 | 84.0 | 67.0 | 47.8 | 67.0 | 82.8 | 79.5 | 62.9 | 44.2 | 41.0 | 48.5 | 62.0 |
| InternVL3.5-8B | 23.5 | 27.6 | 28.0 | 34.5 | 24.7 | 27.9 | 22.4 | 17.0 | 19.7 | 28.2 | 30.0 | 14.2 | 30.1 | 25.4 |
| + DIFT | 43.4 | 42.2 | 36.7 | 37.0 | 33.0 | 30.4 | 41.5 | 39.1 | 37.2 | 35.1 | 30.4 | 28.0 | 41.2 | 36.2 |
| + DIFT + 4DRL | 69.9 | 64.1 | 65.8 | 53.1 | 51.6 | 39.1 | 52.8 | 55.2 | 52.6 | 47.4 | 39.1 | 36.6 | 49.8 | 50.0 |
| InternVL3.5-38B | 25.8 | 27.8 | 29.2 | 34.2 | 24.7 | 28.5 | 26.7 | 16.3 | 23.4 | 29.2 | 32.1 | 15.4 | 31.3 | 26.7 |
| + DIFT | 59.0 | 53.1 | 49.4 | 40.7 | 41.8 | 32.2 | 51.9 | 41.4 | 38.5 | 44.3 | 39.9 | 29.8 | 44.2 | 42.5 |
| + DIFT + 4DRL | 85.5 | 73.4 | 83.5 | 80.2 | 60.4 | 37.4 | 67.9 | 74.7 | 70.5 | 64.9 | 44.9 | 37.3 | 49.8 | 59.4 |
Holistic dynamic understanding on Dyn-BenchDyn-Bench 上的整体动态理解
On Dyn-Bench the three best averages all come from 4DThinker (Table 12). Qwen2.5-VL-7B with both stages reaches 65.9 (+11.6), above GPT-5 (61.4), Gemini-2.5-Pro (58.8) and every dedicated spatial model, including SpaceR-7B (59.2), VST-7B-RL (58.8) and SpatialLadder-3B (56.2); Qwen3-VL-32B reaches 75.4 (+10.9), the best result. The camera–object axis, which requires separating ego-motion from object motion, improves on every base model, by 12.0 to 13.6 points.
在 Dyn-Bench 上,平均分最高的三个结果都来自 4DThinker(表 12)。经过两个阶段训练的 Qwen2.5-VL-7B 达到 65.9(+11.6),超过 GPT-5(61.4)、Gemini-2.5-Pro(58.8)以及所有专门的空间模型,包括 SpaceR-7B(59.2)、VST-7B-RL(58.8)和 SpatialLadder-3B(56.2);Qwen3-VL-32B 达到 75.4(+10.9),为最佳结果。需要把自身运动与物体运动分开的“相机与物体”维度在每个基座上都有提升,幅度为 12.0 到 13.6 分。
Table 12Dyn-Bench accuracy %, from the 4DThinker paper: inter-object, object–scene and camera–object axes. 4DThinker rows are trained from the base model above them; DIFT + 4DRL shaded. Blue marks the best in each column.表 12Dyn-Bench 准确率(%),取自 4DThinker 论文:物体之间、物体与场景、相机与物体三个维度。4DThinker 各行都在其上方的基座模型上训练;DIFT + 4DRL 加底色。蓝色为每列最佳。
| Model模型 | Inter-Obj | Obj-Scene | Cam-Obj | Avg.平均 |
|---|---|---|---|---|
| Proprietary models闭源模型 | ||||
| GPT-5 | 54.7 | 70.2 | 59.2 | 61.4 |
| Gemini-2.5-Pro | 56.1 | 64.4 | 55.8 | 58.8 |
| Spatial understanding models空间理解模型 | ||||
| SpaceR-7B | 56.2 | 72.7 | 48.6 | 59.2 |
| VST-7B-RL | 56.3 | 74.4 | 45.7 | 58.8 |
| Spatial-SSRL-7B | 47.5 | 69.4 | 36.7 | 51.2 |
| SpatialLadder-3B | 52.0 | 72.7 | 44.0 | 56.2 |
| 4DThinker on different base models不同基座上的 4DThinker | ||||
| Qwen2.5-VL-7B | 50.8 | 69.9 | 42.1 | 54.3 |
| + DIFT | 56.3 | 74.4 | 47.8 | 59.5 |
| + DIFT + 4DRL | 63.5 | 79.2 | 54.9 | 65.9 |
| Qwen3-VL-8B | 59.0 | 76.2 | 56.0 | 63.7 |
| + DIFT | 64.1 | 79.0 | 60.8 | 68.0 |
| + DIFT + 4DRL | 70.9 | 84.5 | 68.0 | 74.5 |
| Qwen3-VL-32B | 61.1 | 76.0 | 56.5 | 64.5 |
| + DIFT | 66.3 | 79.8 | 61.5 | 69.2 |
| + DIFT + 4DRL | 73.6 | 84.0 | 68.7 | 75.4 |
| InternVL3.5-8B | 50.8 | 65.3 | 42.7 | 52.9 |
| + DIFT | 56.3 | 69.8 | 48.2 | 58.1 |
| + DIFT + 4DRL | 63.1 | 75.5 | 54.9 | 64.5 |
| InternVL3.5-38B | 49.4 | 64.9 | 44.3 | 52.9 |
| + DIFT | 55.4 | 70.1 | 50.3 | 58.6 |
| + DIFT + 4DRL | 62.9 | 76.6 | 57.9 | 65.8 |
What 3DThinker’s latents encode3DThinker 的潜在 token 编码了什么
Compared with other ways to train与其他训练方式的比较
Table 13 trains Qwen2.5-VL-3B on MindCube-only in several ways. With supervised training alone, 3DThinker reaches 62.7, above raw question–answer SFT (52.3), CoT SFT (53.4) and the best cognitive-map SFT from the MindCube paper (60.8, +3.1%). It trails the cognitive-map baselines on Rotation (44.0 against 49.5 and 47.5), which needs dynamic imagination; the paper reads its supervised stage as mainly static spatial understanding, and Stage 2 adds the dynamic part by optimising whole trajectories. With RL, 3DThinker reaches 75.2, 6.4% above both cognitive-map SFT + RL baselines (70.7), while GRPO on the plain model gives 50.6.
表 13 用几种方式在 MindCube-only 数据上训练 Qwen2.5-VL-3B。仅用监督训练时,3DThinker 达到 62.7,高于原始问答 SFT(52.3)、CoT SFT(53.4)以及 MindCube 论文中最好的认知地图 SFT(60.8,+3.1%)。它在 Rotation 上落后于认知地图基线(44.0 对 49.5 和 47.5),这类题需要动态想象;论文认为监督阶段主要学到的是静态空间理解,阶段 2 通过优化整条轨迹补上动态能力。加入强化学习后,3DThinker 达到 75.2,比两种认知地图 SFT + RL 基线(均为 70.7)高 6.4%;直接在原模型上做 GRPO 只有 50.6。
Table 13Training strategies for Qwen2.5-VL-3B on MindCube-only, MindCube-Tiny accuracy %. The CGMap-FFR-Out rows are the cognitive-map baselines of the MindCube paper, with augmented (camera views included) or plain maps. 3DThinker shaded; blue marks the best in each block.表 13Qwen2.5-VL-3B 在 MindCube-only 数据上的不同训练方式,MindCube-Tiny 准确率(%)。CGMap-FFR-Out 各行是 MindCube 论文中的认知地图基线,分为增强版(含相机视角信息)和普通版地图。3DThinker 加底色;蓝色为每组最佳。
| Training训练方式 | Rotation旋转 | Among穿行 | Around环绕 | Overall总体 |
|---|---|---|---|---|
| Supervised only仅监督训练 | ||||
| raw-QA SFT | 34.5 | 52.5 | 66.0 | 52.3 |
| CoT SFT | 36.0 | 54.3 | 65.2 | 53.4 |
| Aug-CGMap-FFR-Out SFT | 49.5 | 52.5 | 66.4 | 55.2 |
| Plain-CGMap-FFR-Out SFT | 47.5 | 62.3 | 67.6 | 60.8 |
| 3DThinker-S1 | 44.0 | 64.8 | 72.4 | 62.7 |
| With reinforcement learning加入强化学习 | ||||
| GRPO | 36.5 | 49.3 | 64.8 | 50.6 |
| CoT SFT + GRPO | 36.5 | 55.2 | 65.6 | 54.1 |
| Aug-CGMap-FFR-Out SFT + RL | 53.0 | 76.8 | 70.0 | 70.7 |
| Plain-CGMap-FFR-Out SFT + RL | 48.0 | 79.2 | 68.4 | 70.7 |
| 3DThinker-S1+S2 | 55.5 | 81.8 | 75.2 | 75.2 |
Decoding the imagined scene解码想象出的场景
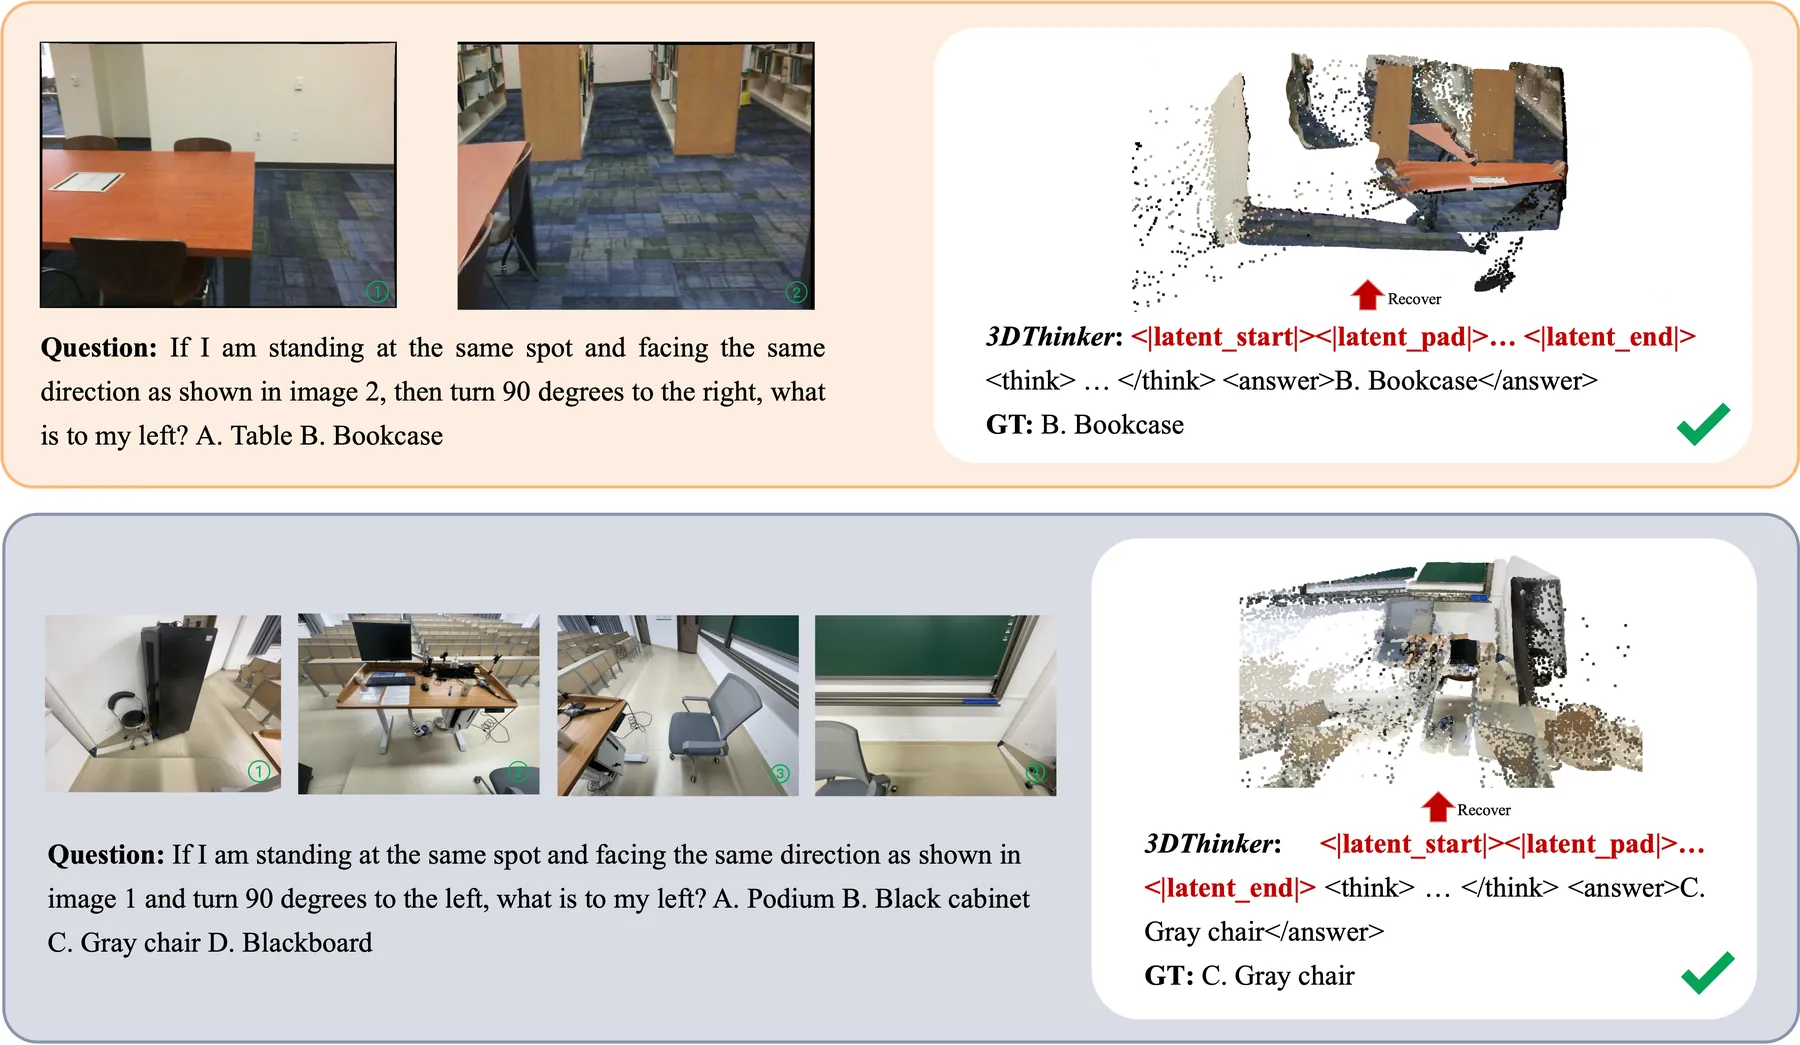
Because the projector maps into VGGT’s feature space, the latents can be turned back into geometry. At inference the paper takes the last-layer hidden states of the special tokens, projects them, and runs VGGT’s DPT head on the result to get a point cloud (Figure 9). The clouds roughly depict the scene, and the clearer regions tend to be the objects the question asks about, which suggests the latents encode a mental scene steered by the prompt. Both examples are answered correctly. Latent reasoning is usually opaque; here the intermediate state can be inspected.
由于投影器映射到 VGGT 的特征空间,潜在 token 可以还原为几何。推理时,论文取特殊 token 的最后一层隐状态,经投影器投影后交给 VGGT 的 DPT 头,得到点云(图 9)。这些点云大致描绘出了场景,而且较清晰的区域往往正是问题所问的物体,说明潜在 token 编码的是受提示引导的心理场景。两个例子都回答正确。潜在推理通常难以解释,这里的中间状态却可以直接查看。
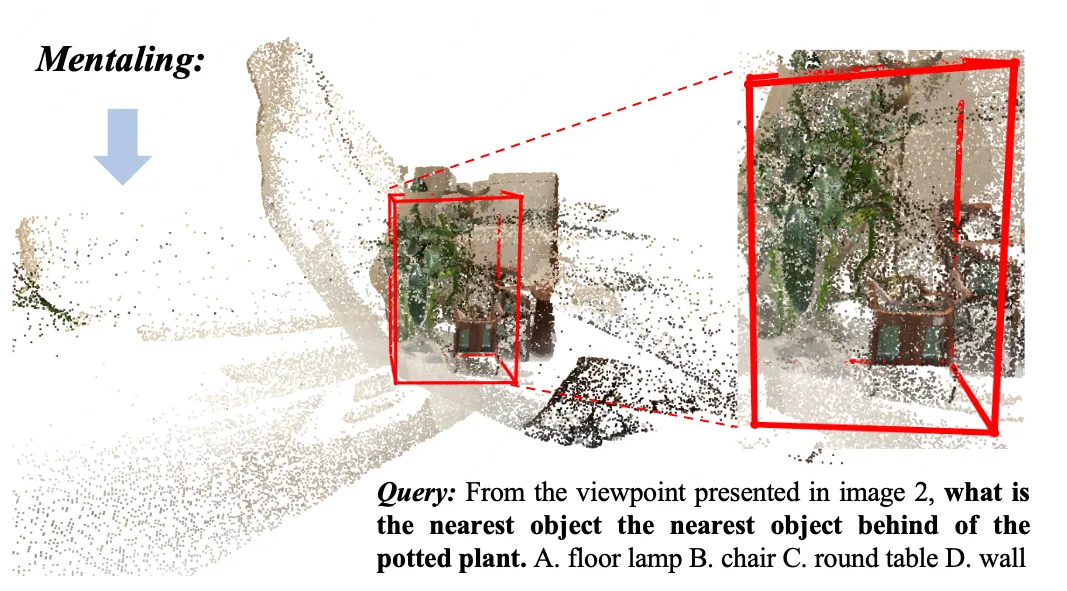
Are the clear regions really prompt-relevant? (Figure 10)清晰区域真的与提示相关吗?(图 10)
The supplementary material measures it: the density of the reconstructed points inside a 3D box around the object in question is 196,494.67 points per unit³, against 1,332.54 for the whole cloud. The repository’s tests/visual_decoder.py does the decoding: it replaces the last entry of VGGT’s aggregated token list with the projected latents and runs VGGT’s camera, depth and point heads.
补充材料对此做了定量测量:在问题所涉物体周围的 3D 框内,重建点的密度为每立方单位 196,494.67 个点,而整个点云只有 1,332.54。仓库中的 tests/visual_decoder.py 实现了解码:它把 VGGT 聚合 token 列表的最后一项替换为投影后的潜在表示,再运行 VGGT 的相机头、深度头和点云头。
Ablations: latent size, token position, projector direction, rewards and L3D (Tables 14–16, Figure 11)消融:潜在 token 数、位置、投影方向、奖励与 L3D(表 14–16、图 11)
Latent size. About twelve tokens work best (Table 14). Fewer limit what the latents can represent; more compromise the model’s natural expression, and it starts repeating <|latent_start|> without reaching an answer: 32 tokens fall to 25.1 and 64 to 15.5.
潜在 token 数。 12 个左右最好(表 14)。太少会限制潜在表示的容量;太多会损害模型自然的表达能力,模型开始反复输出 <|latent_start|>,给不出答案:32 个时降到 25.1,64 个时降到 15.5。
Table 14Number of latent tokens, 3DThinker-S1 on Qwen2.5-VL-3B, MindCube-Tiny overall accuracy %. The released setting, 12, is shaded.表 14潜在 token 数量,Qwen2.5-VL-3B 上的 3DThinker-S1,MindCube-Tiny 总体准确率(%)。开源设置 12 加底色。
| Latent tokens潜在 token 数 | 4 | 8 | 12 | 16 | 32 | 64 |
|---|---|---|---|---|---|---|
| MindCube-Tiny overallMindCube-Tiny 总体 | 60.2 | 60.6 | 62.7 | 59.9 | 25.1 | 15.5 |
Where the block goes. Between <think> and </think> the latents can resemble character features, producing garbled text and early stops: 42.0 against 75.2 (Table 15). At the end, after </answer>, they score 74.3; isolated from the text at either end, they work.
放在哪里。 放在 <think> 与 </think> 之间时,潜在表示可能与某些字符特征相似,导致乱码和提前终止:42.0 对 75.2(表 15)。放在末尾(</answer> 之后)得到 74.3;只要与文本隔开,放在开头或末尾都可行。
Projector direction. Compressing VGGT’s features into the VLM’s space, for example by adaptive average pooling, needs no trained projector but cannot be decoded back into 3D, and scores slightly lower (74.1 vs 75.2) (Figure 11).
投影方向。 把 VGGT 的特征压缩到 VLM 的空间(例如用自适应平均池化)不需要训练投影器,但无法解码回 3D,得分也略低(74.1 对 75.2)(图 11)。
Rewards. Dropping the format reward barely matters (74.8). Dropping r3D costs 6.9 points (68.3), as the latents lose their stable constraint; dropping the answer reward, the only ground-truth signal, costs 11.0 (64.2). Even without r3D, Stage 2 still improves on Stage 1 by 8.93% (68.3 vs 62.7), so the RL stage does not need the teacher.
奖励。 去掉格式奖励几乎没有影响(74.8)。去掉 r3D 损失 6.9 分(68.3),因为潜在表示失去了稳定的约束;去掉答案奖励这个唯一的真值信号,损失 11.0 分(64.2)。即使没有 r3D,阶段 2 仍比阶段 1 高 8.93%(68.3 对 62.7),可见强化学习阶段并不依赖教师模型。
Table 15Design ablations for 3DThinker-S1+S2 on Qwen2.5-VL-3B, MindCube-Tiny overall accuracy %. Each column changes one thing from the full model, which places the block at the beginning, projects VLM → VGGT and uses all three rewards.表 153DThinker-S1+S2(Qwen2.5-VL-3B)的设计消融,MindCube-Tiny 总体准确率(%)。每一列只改动完整模型的一处设计;完整模型把潜在 token 段放在开头,投影方向为 VLM → VGGT,并使用全部三项奖励。
| 3D tokens placed3D token 位置 | Projector投影方向 | Stage-2 rewards阶段 2 奖励 | Full完整 | ||||
|---|---|---|---|---|---|---|---|
| Middle中间 | End末尾 | VGGT → VLM | w/o rformat去掉 rformat | w/o rans去掉 rans | w/o r3D去掉 r3D | ||
| MindCube-Tiny overallMindCube-Tiny 总体 | 42.0 | 74.3 | 74.1 | 74.8 | 64.2 | 68.3 | 75.2 |
The 3D loss. Removing VGGT from Stage 1, so that only the cross-entropy trains the tokens around the special tokens, drops MindCube-Tiny from 62.7 to 54.1 (Table 16). That is still slightly above CoT SFT (53.4): the special tokens alone add some representational room, but the geometry comes from the teacher.
3D 损失。 在阶段 1 中去掉 VGGT、只用交叉熵训练特殊 token 之外的 token 时,MindCube-Tiny 从 62.7 降到 54.1(表 16)。这仍略高于 CoT SFT(53.4):特殊 token 本身带来了一些表示上的余地,但几何信息来自教师模型。
Table 16The 3D alignment loss in Stage 1, Qwen2.5-VL-3B, MindCube-Tiny accuracy %, from the 3DThinker paper’s supplementary material.表 16阶段 1 中的 3D 对齐损失,Qwen2.5-VL-3B,MindCube-Tiny 准确率(%),取自 3DThinker 论文补充材料。
| Stage 1 loss阶段 1 损失 | Rotation旋转 | Among穿行 | Around环绕 | Overall总体 |
|---|---|---|---|---|
| w/o L3D (CE only)去掉 L3D(仅 CE) | 35.0 | 55.1 | 66.8 | 54.1 |
| Full: Ltext + L3D完整:Ltext + L3D | 44.0 | 64.8 | 72.4 | 62.7 |
What 4D imagery adds4D 想象带来了什么
Compared with other ways to train与其他训练方式的比较
The ablations use Qwen2.5-VL-3B on DSR-Bench. With supervised training alone, fine-tuning on the raw questions (25.1) or on text-only reasoning (26.8) barely moves the base model (24.6), while DIFT reaches 31.1, 4.3 points above CoT SFT (Table 17). With reinforcement learning, plain GRPO gives 27.1 and CoT SFT + GRPO 29.7, against 34.2 for DIFT + 4DRL. The paper’s reading: reasoning in discrete text alone hits an expressiveness ceiling that the latent imagery lifts.
消融实验使用 Qwen2.5-VL-3B 和 DSR-Bench。仅用监督训练时,在原始问答上微调(25.1)或在纯文本推理上微调(26.8)几乎没有改变基座模型(24.6),而 DIFT 达到 31.1,比 CoT SFT 高 4.3 分(表 17)。加入强化学习后,直接做 GRPO 得到 27.1,CoT SFT + GRPO 得到 29.7,DIFT + 4DRL 则达到 34.2。论文的解读是:只用离散文本推理会遇到表达能力的上限,潜在想象打破了这个上限。
Table 17Training strategies for Qwen2.5-VL-3B, DSR-Bench accuracy %, from the 4DThinker paper. 4DThinker shaded; blue marks the best in each block.表 17Qwen2.5-VL-3B 的不同训练方式,DSR-Bench 准确率(%),取自 4DThinker 论文。4DThinker 加底色;蓝色为每组最佳。
| Training训练方式 | DSR-Bench |
|---|---|
| Supervised only仅监督训练 | |
| Raw QA SFT | 25.1 |
| CoT SFT | 26.8 |
| DIFT | 31.1 |
| With reinforcement learning加入强化学习 | |
| GRPO | 27.1 |
| CoT SFT + GRPO | 29.7 |
| DIFT + 4DRL | 34.2 |
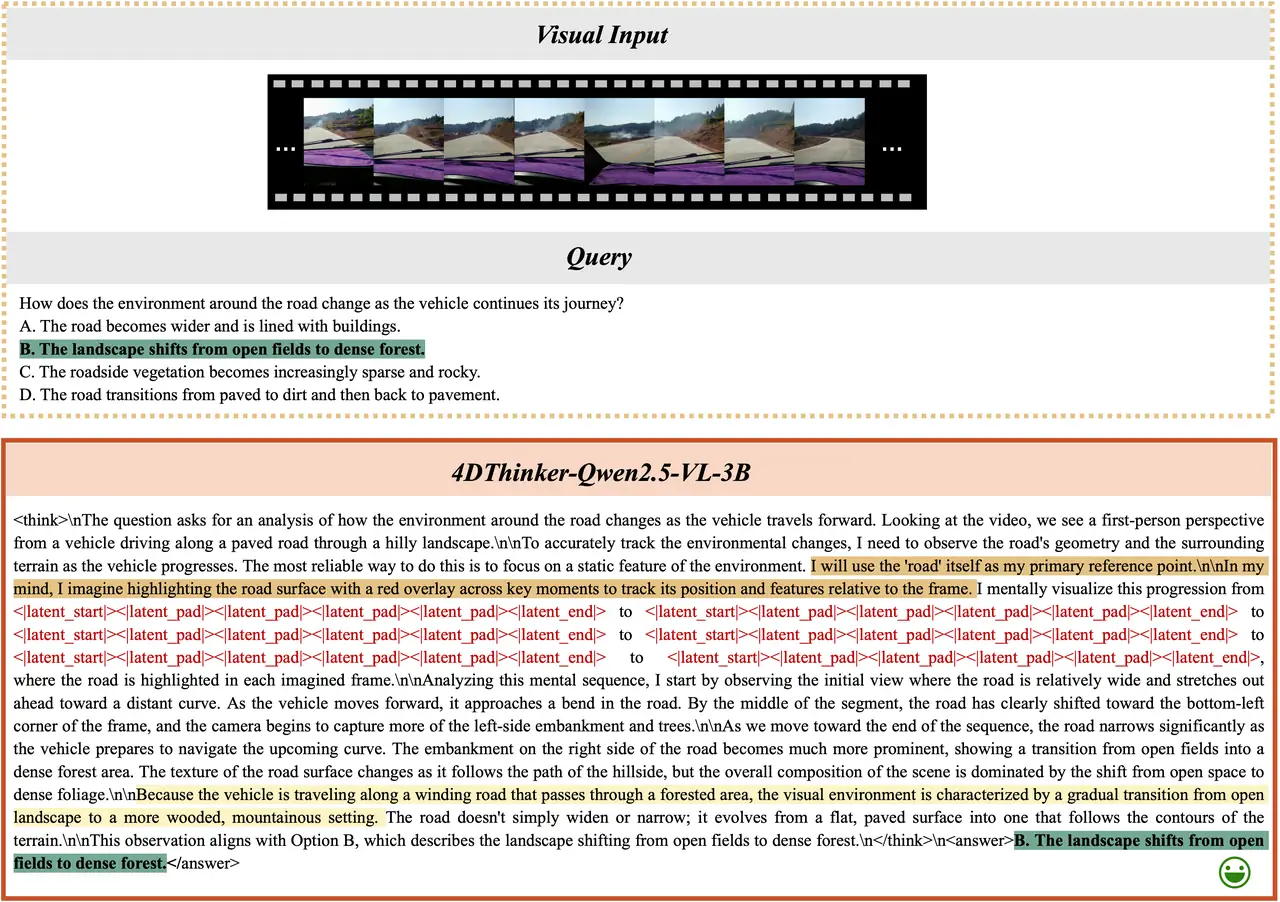
The imagery in action想象过程示例
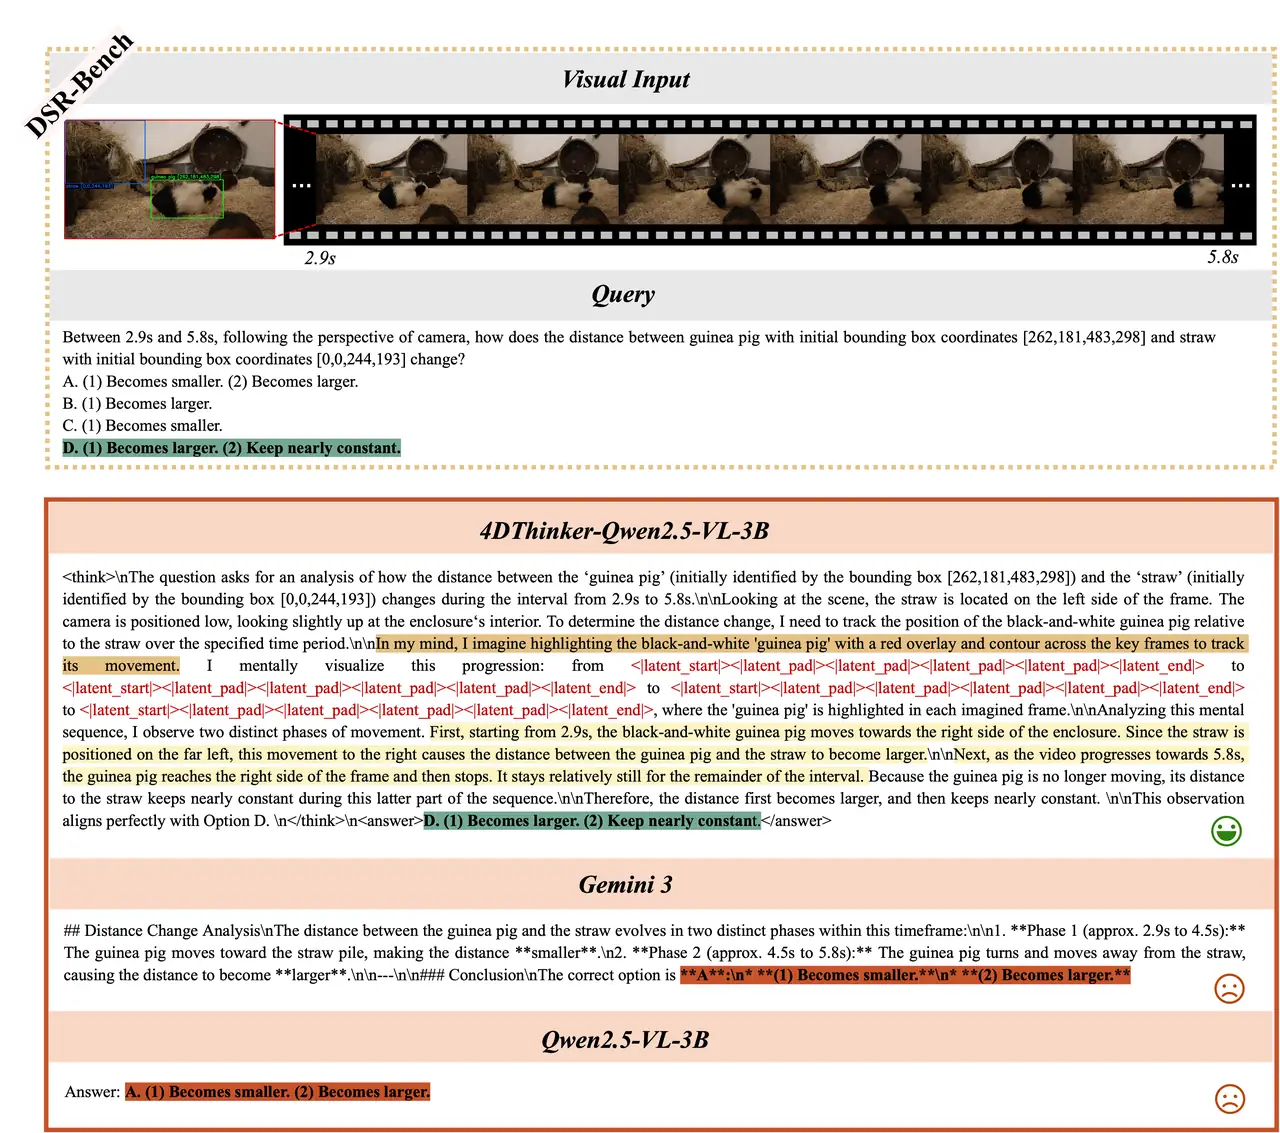
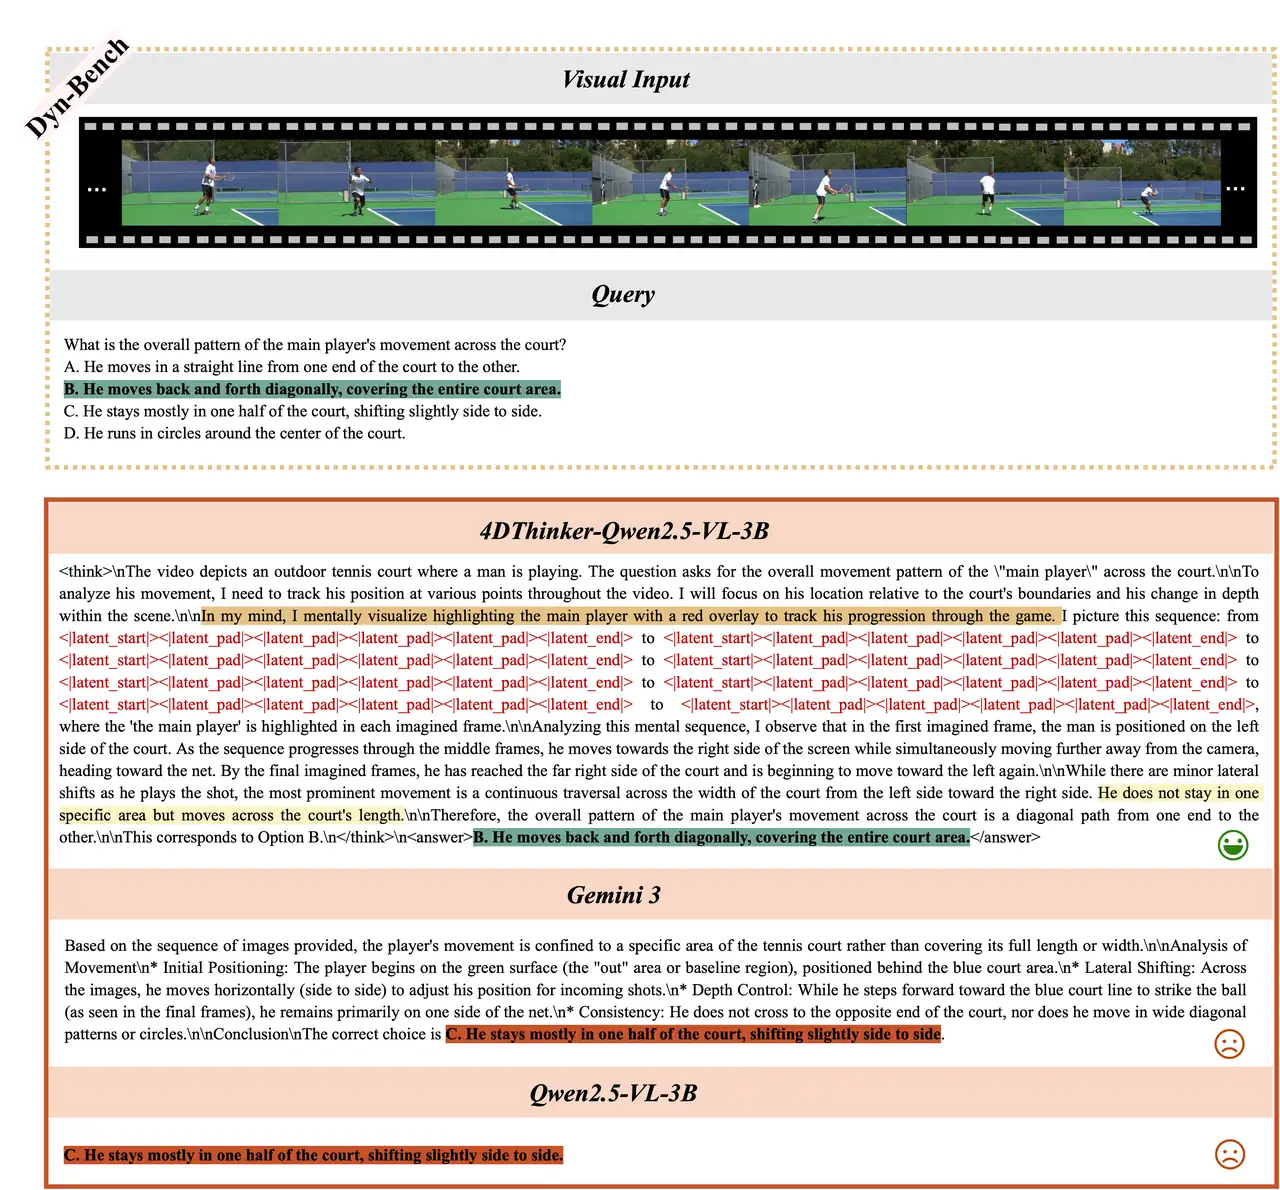
In the paper’s examples the model first states its strategy, then writes a few latent blocks as its imagined frames, and then derives the answer. In Figure 12, a DSR-Bench question, it splits a guinea pig’s motion into two phases, the distance first growing and then staying constant, where Gemini-3 and the base Qwen2.5-VL-3B both answer wrongly. In Figure 13, from Dyn-Bench, it follows a player diagonally across the whole court, while both baselines conclude from local frames that he stays in one half.
在论文给出的例子中,模型先说明推理策略,再写出几段潜在 token 作为想象中的画面,然后得出答案。图 12 是一道 DSR-Bench 题,模型把一只豚鼠的运动分成两个阶段:距离先变大、后保持不变,而 Gemini-3 和基座 Qwen2.5-VL-3B 都答错了。图 13 来自 Dyn-Bench,模型跟踪一名球员沿对角线穿过整个球场,而两个基线都根据局部画面认为他一直待在半场内。
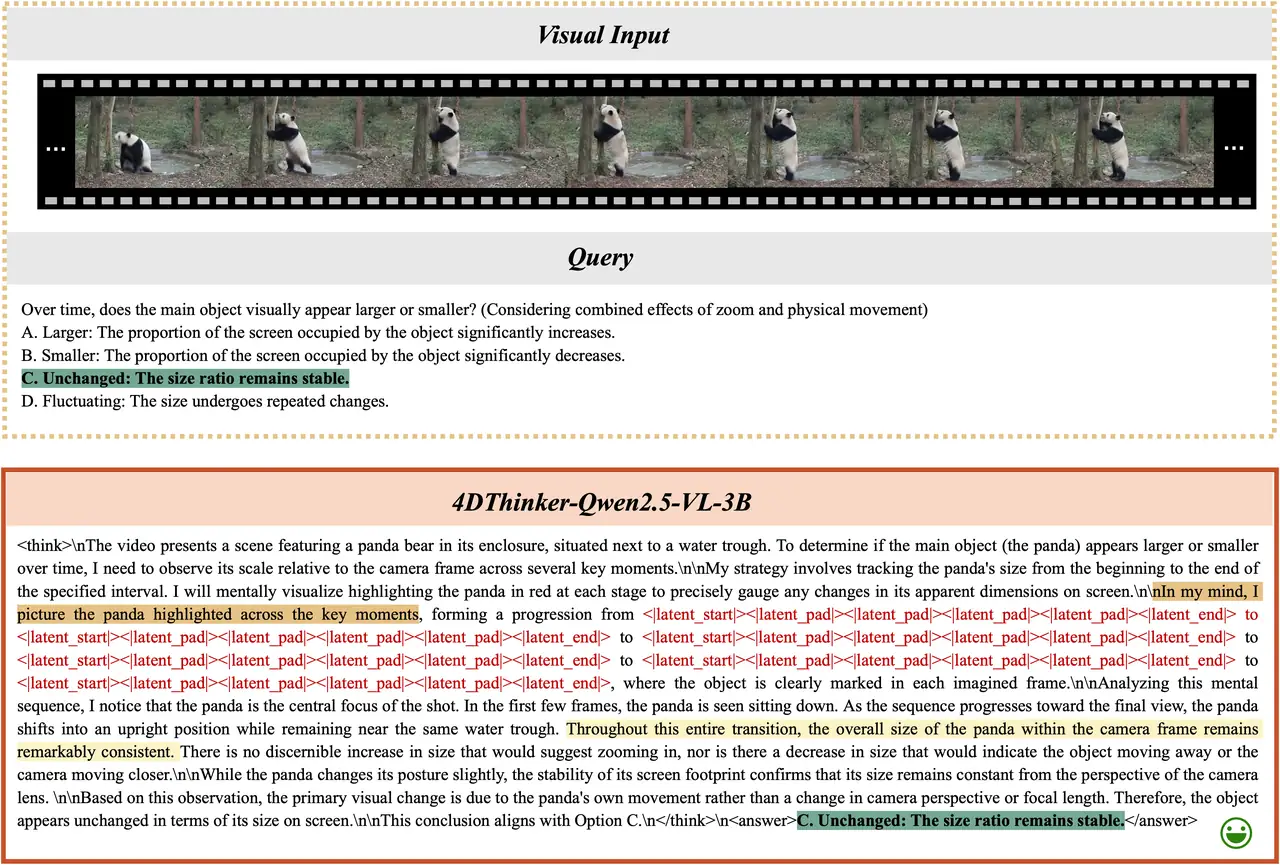
Two more examples: posture versus zoom, and a driving scene (Figures 14, 15)另外两个例子:姿态变化与镜头缩放、驾驶场景(图 14、图 15)
Ablations: losses, rewards and the number of latent tokens (Tables 18, 19)消融:损失、奖励与潜在 token 数(表 18、表 19)
Losses and rewards. Without Lce the model loses coherent text and falls to 19.3. Without Lsim it drops to 28.5: the latents are no longer tied to anything visual. Of the rewards, removing Racc costs more (32.0) than removing Rfmt (33.4), since accuracy shapes the reasoning while the format reward mainly keeps the structure (Table 18).
损失与奖励。 去掉 Lce 后模型无法生成通顺的文本,降到 19.3。去掉 Lsim 后降到 28.5:潜在 token 不再与任何视觉内容绑定。两项奖励中,去掉 Racc 的损失(32.0)大于去掉 Rfmt(33.4),因为准确率奖励塑造推理本身,格式奖励主要保证结构合规(表 18)。
Table 18Removing one loss or reward from 4DThinker (DIFT + 4DRL, Qwen2.5-VL-3B), DSR-Bench accuracy %.表 18从 4DThinker(DIFT + 4DRL,Qwen2.5-VL-3B)中去掉一项损失或奖励后的 DSR-Bench 准确率(%)。
| Variant变体 | DSR-Bench |
|---|---|
| Full (DIFT + 4DRL)完整(DIFT + 4DRL) | 34.2 |
| w/o Lsim去掉 Lsim | 28.5 |
| w/o Lce去掉 Lce | 19.3 |
| w/o Rfmt去掉 Rfmt | 33.4 |
| w/o Racc去掉 Racc | 32.0 |
Latent tokens per block. DIFT accuracy rises from K = 1 (29.6) to K = 4 (31.1) and then slips (30.8 at K = 8, 29.3 at K = 16), which the paper attributes to too many latent tokens diluting the textual context (Table 19). 3DThinker’s single block peaked at twelve tokens.
每段的潜在 token 数。 DIFT 的准确率从 K = 1(29.6)升到 K = 4(31.1),之后略有下降(K = 8 为 30.8,K = 16 为 29.3),论文认为潜在 token 过多会稀释文本上下文(表 19)。3DThinker 的单段潜在 token 在 12 个时最好。
Table 19Latent tokens per imagery block K in DIFT (Qwen2.5-VL-3B), DSR-Bench accuracy %. The released setting, K = 4, is shaded.表 19DIFT 中每段想象 token 数 K(Qwen2.5-VL-3B),DSR-Bench 准确率(%)。开源设置 K = 4 加底色。
| Latent tokens K潜在 token 数 K | 1 | 2 | 4 | 8 | 16 |
|---|---|---|---|---|---|
| DSR-Bench (DIFT)DSR-Bench(DIFT) | 29.6 | 30.4 | 31.1 | 30.8 | 29.3 |
Limitations局限
3DThinker
The 3DThinker paper shows a failure case (Figure 16). From two indoor views, 3DThinker misplaces the object at the back, and the decoded point cloud shows why: the wall with two photographs sits on the right of the window view when it should be on the left. Two views constrain the scene too little, the reconstruction goes wrong and the reasoning follows it. With extremely sparse views, the authors suggest bringing in other information as future work.
3DThinker 论文给出了一个失败案例(图 16)。根据两张室内视角图,3DThinker 判断错了后方物体的位置,解码出的点云揭示了原因:挂着两幅照片的那面墙被放在了窗户视角的右侧,而它本应在左侧。两个视角对场景的约束太少,重建出错,推理也随之出错。对于极度稀疏的视角,作者建议今后引入其他信息来补充。
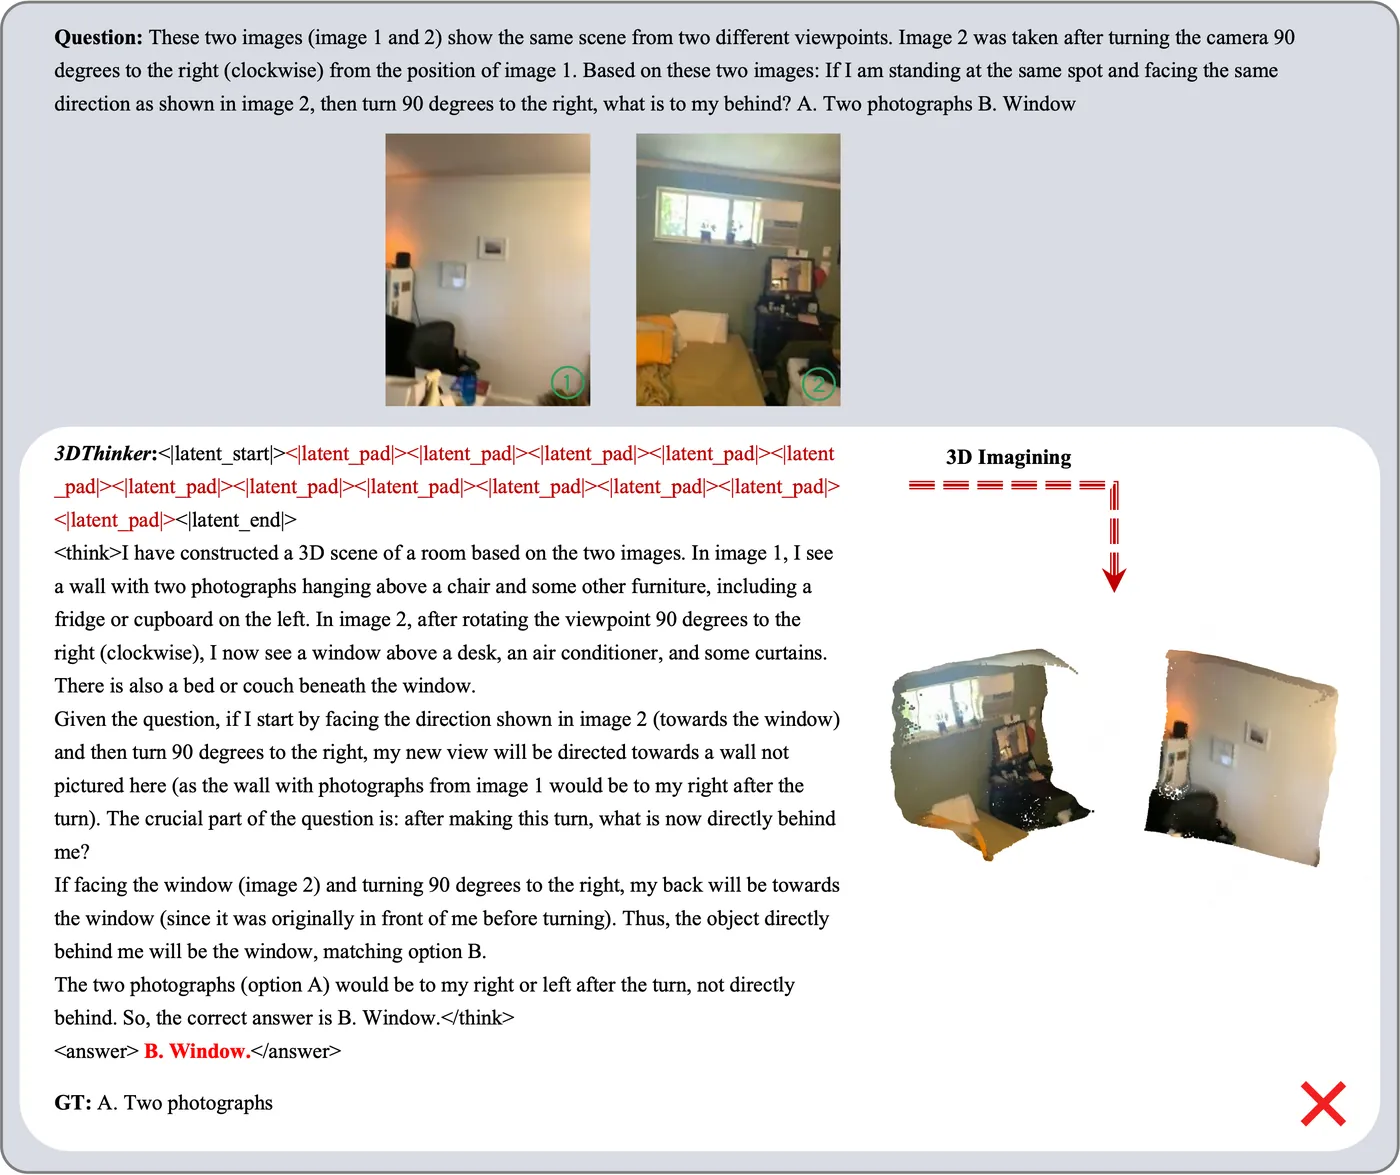
- Training depends on VGGT. Stage 1 needs its features as targets, and the reward r3D uses them in Stage 2; inference does not.
- The Stage 1 traces are written by GPT-4.1, so “annotation-free” means free of manual geometric annotation, not free of a stronger model.
- The latent block is fragile in two ways: placed inside the reasoning it breaks the text, and 32 or more tokens collapse the output.
- Travel-time questions in Ego3D-Bench do not benefit from Stage 2: on six of the eight models in Table 4 it leaves them at or slightly below Stage 1.
- 训练依赖 VGGT。阶段 1 需要它的特征作为目标,阶段 2 的 r3D 奖励也要用到它;推理时则不需要。
- 阶段 1 的推理链由 GPT-4.1 生成,因此“无需标注”指的是不需要人工几何标注,而不是不依赖更强的模型。
- 潜在 token 段在两方面比较脆弱:放进推理文本中间会破坏文本,数量达到 32 个及以上时输出会崩溃。
- Ego3D-Bench 中的行程时间题无法从阶段 2 获益:在表 4 的 8 个模型中有 6 个,阶段 2 在这一项上与阶段 1 持平或略低。
4DThinker
The 4DThinker paper names two limitations, and its setup implies a third.
4DThinker 论文指出了两点局限,其设置还隐含第三点。
- The data pipeline relies on off-the-shelf estimators such as MegaSaM, whose errors can propagate into the training data; 4DRL partly mitigates this, and more robust geometric priors could improve the data.
- Evaluation covers multiple-choice benchmarks only; open-ended generation such as embodied planning remains open.
- The questions, landmark choices and reasoning traces come from Gemini-3-pro and the masks from SAM3, so here too “annotation-free” means free of human labels, not of stronger models.
- 数据流程依赖 MegaSaM 等现成的估计器,它们的误差可能传入训练数据;4DRL 能部分缓解这一问题,更可靠的几何先验可以进一步提升数据质量。
- 评测只覆盖选择题基准;具身规划等开放式生成任务仍待解决。
- 问题、地标选择和推理链来自 Gemini-3-pro,掩码来自 SAM3,因此这里的“无需标注”同样指不需要人工标注,而不是不依赖更强的模型。
Open-source resources开源资源
Both repositories are Apache-2.0. 3DThinker’s released model is the Stage 1 checkpoint of Qwen2.5-VL-3B trained on MindCube’s training data and tested on MindCube-Tiny (Apache-2.0); its README notes that the models in Table 5 were trained on different data. The 3DThinker-10K data is CC BY-NC 4.0, and so are the VGGT-1B weights that its Stage 1 and r3D reward rely on. 4DThinker releases Qwen2.5-VL-3B checkpoints after DIFT and after 4DRL and its training data, both marked Apache-2.0 on Hugging Face; the data is built on SpatialVID, whose own licence is CC BY-NC-SA 4.0, and on DSR_Suite-Data.
两个代码仓库都采用 Apache-2.0。3DThinker 发布的模型是在 MindCube 训练数据上训练、在 MindCube-Tiny 上测试的 Qwen2.5-VL-3B 阶段 1 检查点(Apache-2.0);其 README 说明表 5 中的模型使用了不同的训练数据。3DThinker-10K 数据采用 CC BY-NC 4.0,其阶段 1 和 r3D 奖励所依赖的 VGGT-1B 权重同样采用 CC BY-NC 4.0。4DThinker 发布了 Qwen2.5-VL-3B 在 DIFT 与 4DRL 之后的检查点及训练数据,在 Hugging Face 上均标注为 Apache-2.0;这些数据基于 SpatialVID(其许可为 CC BY-NC-SA 4.0)和 DSR_Suite-Data 构建。
3DThinker
4DThinker
3DThinker builds on and is tested with3DThinker 的依赖与评测
4DThinker builds on and is tested with4DThinker 的依赖与评测
3DThinker environment setup3DThinker 环境配置
The README uses three conda environments: one per training stage and one LLaMA-Factory environment for merging weights. Stage 2 must use the same customised transformers as Stage 1 (3dthinker/stage1/transformers, replacing transformers 4.49.0); if the installed trl conflicts, copy the bundled 3dthinker/stage2/package/trl into the environment’s site-packages. envs/requirements_*.txt list the full environments.
README 使用三套 conda 环境:两个训练阶段各一套,再加一套用于合并权重的 LLaMA-Factory 环境。阶段 2 必须使用与阶段 1 相同的定制版 transformers(3dthinker/stage1/transformers,替换 transformers 4.49.0);如果已安装的 trl 版本冲突,把自带的 3dthinker/stage2/package/trl 复制到该环境的 site-packages 中。完整环境见 envs/requirements_*.txt。
git clone https://github.com/zhangquanchen/3DThinker.git
cd 3DThinker

# Stage 1
conda create -n 3DThinker-stage1 python=3.10 -y && conda activate 3DThinker-stage1
pip install -r envs/requirements_stage1.txt

# Stage 2 (then swap in the Stage 1 transformers)
conda create -n 3DThinker-stage2 python=3.10 -y && conda activate 3DThinker-stage2
bash 3dthinker/stage2/setup.sh

# SFT: LLaMA-Factory, for weight merging
conda create -n SFT python=3.10 -y && conda activate SFT
cd SFT/env
pip install -e ".[torch,metrics]" --no-build-isolation
Evaluating 3DThinker on MindCube-Tiny在 MindCube-Tiny 上评测 3DThinker
Evaluation follows MindCube’s official code: organise the benchmark as it requires, then run two scripts in eval/. The first runs inference with scripts/run_inference_clean.py on MindCube_tinybench_raw_qa.jsonl, the second scores the responses with scripts/run_evaluation.py -t basic. Other base models have their own eval_*.py (InternVL, LLaVA, Qwen3, closed models). The repository also ships the Qwen2.5-VL-3B responses on MindCube-Tiny under data/.
评测沿用 MindCube 的官方代码:按其要求整理基准数据,然后运行 eval/ 下的两个脚本。第一个用 scripts/run_inference_clean.py 在 MindCube_tinybench_raw_qa.jsonl 上推理,第二个用 scripts/run_evaluation.py -t basic 给回答打分。其他基座模型各有对应的 eval_*.py(InternVL、LLaVA、Qwen3 以及闭源模型)。仓库的 data/ 目录下还附有 Qwen2.5-VL-3B 在 MindCube-Tiny 上的回答。
cd eval
sh eval_mindcube.sh   # inference: scripts/run_inference_clean.py --model-type qwen2.5vl ...
sh get_result.sh      # scoring:   scripts/run_evaluation.py -t basic ...
Citation引用
@inproceedings{chen2026think,
  title     = {Think with 3D: Geometric Imagination Grounded Spatial Reasoning
               from Limited Views},
  author    = {Chen, Zhangquan and Zhang, Manyuan and Yu, Xinlei and Luo, Xufang and
               Sun, Mingze and Pan, Zihao and An, Xiang and Feng, Yan and Pei, Peng and
               Cai, Xunliang and Huang, Ruqi},
  booktitle = {CVPR},
  year      = {2026}
}
@article{chen20264dthinker,
  title     = {4DThinker: Thinking with 4D Imagery for Dynamic Spatial Understanding},
  author    = {Chen, Zhangquan and Zhang, Manyuan and Yu, Xinlei and An, Xiang and
               Li, Bo and Xie, Xin and Wang, ZiDong and Sun, Mingze and Chen, Shuang and
               Li, Hongyu and Hu, Xiaobin and Huang, Ruqi},
  journal   = {arXiv preprint arXiv:2605.05997},
  year      = {2026}
}
Authors作者
3DThinker · Zhangquan Chen1, Manyuan Zhang2†, Xinlei Yu3, Xufang Luo4, Mingze Sun1, Zihao Pan2, Xiang An5, Yan Feng2, Peng Pei2, Xunliang Cai2, Ruqi Huang1†
1 Tsinghua Shenzhen International Graduate School, Tsinghua University · 2 Meituan · 3 National University of Singapore · 4 Beihang University · 5 LMMs-Lab. † Corresponding authors. Zhangquan Chen did the work during an internship at Meituan.1 清华大学深圳国际研究生院 · 2 美团 · 3 新加坡国立大学 · 4 北京航空航天大学 · 5 LMMs-Lab。† 通讯作者。本工作由 Zhangquan Chen 在美团实习期间完成。
4DThinker · Zhangquan Chen1,2, Manyuan Zhang2,3†, Xinlei Yu4, Xiang An5, Bo Li5, Xin Xie3, ZiDong Wang2,3, Mingze Sun1, Shuang Chen6, Hongyu Li2,3, Xiaobin Hu4, Ruqi Huang1†
1 Tsinghua University, SIGS · 2 Meituan · 3 The Chinese University of Hong Kong · 4 National University of Singapore · 5 LMMs-Lab · 6 University of California, Los Angeles. † Corresponding authors.1 清华大学深圳国际研究生院 · 2 美团 · 3 香港中文大学 · 4 新加坡国立大学 · 5 LMMs-Lab · 6 加州大学洛杉矶分校。† 通讯作者。